Amazon Textract vs Amazon Bedrock (Claude or Bedrock Data Automation): which one should read the documents in your S3 bucket?
Textract turns a scanned page into structured JSON with coordinates and confidence scores, billed per page. Claude on Bedrock answers a question about a file, billed per token. Here is what each one accepts, what it returns, what it costs, and when to chain them.
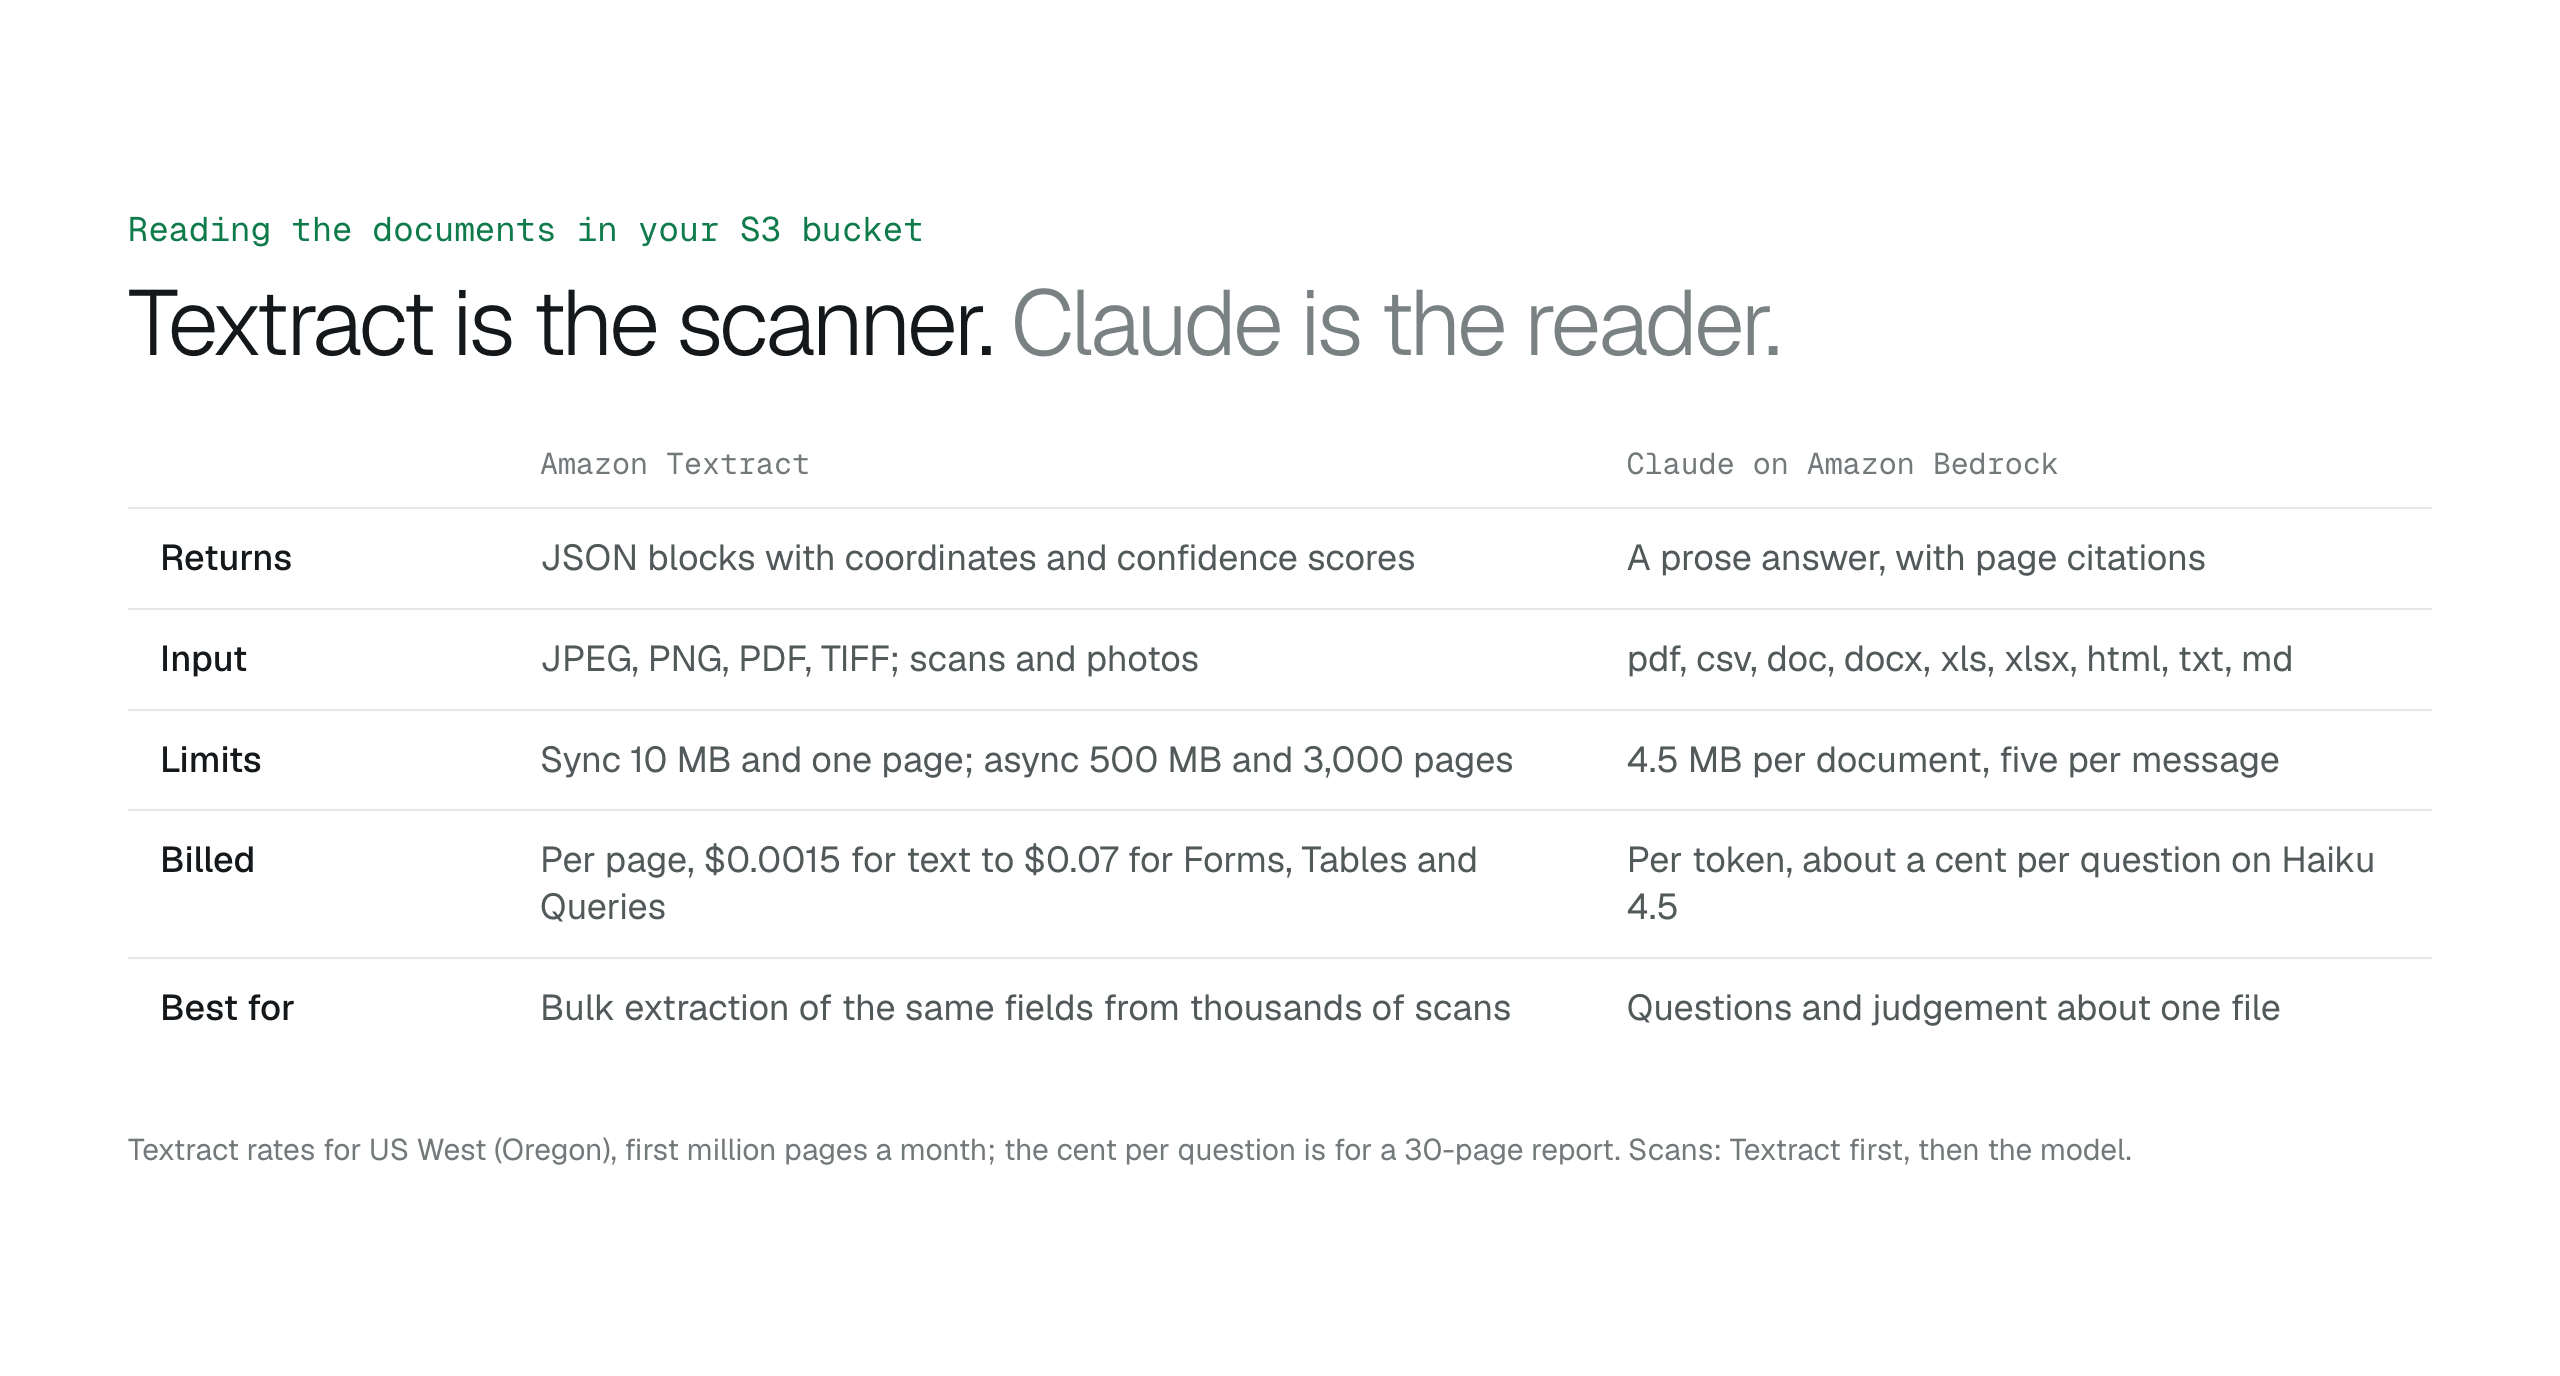
Textract is the scanner: per page, any image or scanned PDF up to 3,000 pages asynchronously, and JSON with coordinates and confidence for forms, tables, queries and signatures. Claude on Bedrock is the reader: per token, text-native PDFs and Office files up to 4.5 MB, and a cited answer to a question nobody wrote down in advance. Use Textract for bulk extraction and scans, a model for questions and judgement, and chain them when the input is paper and the question is open. Bedrock Data Automation is the packaged version of that chain, at about $0.010 a page for layout and $0.040 a page for blueprint fields.
Two AWS services will read a PDF sitting in your S3 bucket, and people searching for "Amazon Textract" are often deciding between them. Textract is optical character recognition with structure: it finds the words, the key-value pairs, the tables and the signatures on a page and hands back JSON with coordinates and confidence scores. Claude on Amazon Bedrock is a language model: you hand it the file and a question and it answers in prose, with a page citation if you ask for one.
They are priced differently, accept different inputs, and return different things. The right choice depends on whether you want fields pulled out of ten thousand invoices or an answer about the contract someone has open. Often the honest answer is both, in that order. A third option, Amazon Bedrock Data Automation, packages extraction and a model behind one API, and the Bedrock Data Automation vs Textract question gets its own section below.
What each one returns
Textract returns Block objects. For a plain text detection call that means PAGE, LINE and WORD blocks, each with a bounding box and a confidence score. Turn on the analysis features and you also get KEY_VALUE_SET blocks for form fields, TABLE and CELL blocks for tables, QUERY and QUERY_RESULT blocks for the questions you asked, SIGNATURE blocks for where someone signed, and LAYOUT blocks that label paragraphs, titles, headers, footers and figures in reading order.
That output is built for pipelines. Every value has a location on the page and a score you can threshold, so a downstream system can accept "Invoice total: 4,820.00" at 99 percent and route it to a human at 70 percent. What Textract does not do is reason. Ask it "which of these line items are taxable" and you have to write that logic yourself.
Claude returns the opposite shape. The Bedrock Converse API takes the document and a question and gives back a text answer. With citations enabled, the answer arrives as citationsContent blocks that each name the page range the passage came from. You can ask for structured JSON in the prompt, but it is a generated answer, not a measured one, and there is no confidence score or bounding box.
- Textract: words, lines, form fields, table cells, query answers, signatures, layout, each with geometry and confidence.
- Claude: a prose answer, optionally with page citations into the document you sent.
- Textract reads scans; Claude reasons about content.
File limits that decide the architecture
Textract accepts JPEG, PNG, PDF and TIFF. The synchronous operations take a file of up to 10 MB and, for PDF and TIFF, one page only. Multi-page documents go through the asynchronous operations, which accept PDF and TIFF up to 500 MB and 3,000 pages, read the file from S3, and notify an SNS topic when the job finishes. PDFs cannot be password protected and XFA forms are not supported. Both services read the object directly, so files in Glacier Flexible Retrieval or Deep Archive need restoring from the archive tier first.
Because Textract is OCR, it does not care whether the PDF has a text layer. A photographed receipt, a faxed purchase order or a scanned signature page all work, in English, French, German, Italian, Portuguese and Spanish, with handwriting in English only. Text has to be at least 15 pixels tall, which is about 8 point at 150 DPI, and vertical text is not supported.
Claude through Converse accepts pdf, csv, doc, docx, xls, xlsx, html, txt and md, up to five documents per message and 4.5 MB each. That covers Office files Textract cannot read at all. But citations work on extracted text, so a scanned PDF with no text layer has nothing to cite, and anything over 4.5 MB has to be split or summarised in stages.
Ask questions about S3 documents with Claude on Amazon BedrockHow to preview files in Amazon S3 without downloading them
- Textract sync: 10 MB, one page for PDF and TIFF.
- Textract async: 500 MB and 3,000 pages, S3 input, SNS notification.
- Converse: 4.5 MB per document, five per message, Office formats included.
- Scans: Textract yes, Claude citations no.
Example: ask Textract a question about a multi-page PDF in S3
Textract Queries let you ask for a field in plain language rather than parsing key-value pairs yourself, up to 15 queries per page synchronously and 30 asynchronously. Query detection is English only. The script below starts an asynchronous analysis on a PDF in S3, polls for the result, and prints each query with its answer and confidence. Production code should subscribe to the SNS topic instead of polling.
cat > textract_queries.py <<'EOF'
import time
import boto3

textract = boto3.client("textract", region_name="us-east-1")

job = textract.start_document_analysis(
    DocumentLocation={"S3Object": {"Bucket": "amzn-s3-demo-bucket", "Name": "invoices/inv-10422.pdf"}},
    FeatureTypes=["QUERIES", "TABLES"],
    QueriesConfig={"Queries": [
        {"Text": "What is the invoice total?", "Alias": "total"},
        {"Text": "What is the payment due date?", "Alias": "due_date"},
    ]},
)

blocks, token = [], None
while True:
    kwargs = {"JobId": job["JobId"]}
    if token:
        kwargs["NextToken"] = token
    page = textract.get_document_analysis(**kwargs)
    if page["JobStatus"] == "IN_PROGRESS":
        time.sleep(5)
        continue
    if page["JobStatus"] != "SUCCEEDED":
        raise SystemExit(page["JobStatus"])
    blocks += page["Blocks"]
    token = page.get("NextToken")
    if not token:
        break

by_id = {b["Id"]: b for b in blocks}
for b in blocks:
    if b["BlockType"] == "QUERY":
        for rel in b.get("Relationships", []):
            for rid in rel["Ids"]:
                ans = by_id[rid]
                print(b["Query"]["Alias"], "=", ans["Text"], f"({ans['Confidence']:.0f}%)")
EOF
python3 textract_queries.py
What each one costs
Textract bills per page, and the price depends on which features you turn on. In US West (Oregon) for the first million pages a month, plain text detection is $0.0015 a page. Tables and Queries are $0.015 a page each, Forms is $0.05, Signatures $0.0035, and Layout is free when combined with Tables. Stack Forms, Tables and Queries on one call and the page costs $0.07. Invoices and receipts through AnalyzeExpense are $0.01 a page. Prices drop past a million pages, and new accounts get three months of 1,000 text pages and 100 analysis pages a month free. Check the pricing page before you budget; these figures are from October 2026.
Claude on Bedrock bills per token, in and out, and the document is most of the input. Our measurements for a 30-page text report came to about a cent per question on Claude Haiku 4.5 without prompt caching, and a tenth of that for follow-up questions with caching on. Amazon Nova Lite answered the same question for well under a tenth of a cent.
Put side by side, running Textract Queries over that 30-page report costs about $0.45 for up to 30 questions on every page, with coordinates and confidence, whether or not anyone reads the result. Asking Claude one question costs about a cent and returns one answer. Textract wins when you need every field from every page; a model wins when a person wants one answer now.
Amazon Bedrock pricing for document Q&AWhat a document chat costs on Amazon Bedrock, by model, with prompt caching
- Textract: per page, from $0.0015 for text to $0.07 for Forms, Tables and Queries together.
- Claude: per token, roughly a cent per question about a 30-page report on Haiku 4.5.
- Textract is paid whether or not anyone looks; a model is paid when someone asks.
When to use Textract
Choose Textract when the input is paper that has been scanned or photographed, when you need a value for every document in a batch, or when the result feeds a system that needs a confidence score and a location on the page. Accounts payable, claims intake, onboarding forms and lending packages are the classic cases, and Textract has dedicated AnalyzeExpense, AnalyzeID and Analyze Lending operations for them.
It is also the right tool when a human must be able to verify the extraction visually. A bounding box lets your review screen draw a rectangle around the field it read, which is a stronger audit trail than a sentence.
- Scanned or photographed documents with no text layer.
- Bulk extraction of the same fields from thousands of files.
- Downstream validation that needs confidence scores and coordinates.
- Invoices, receipts, US identity documents and mortgage packages.
When to use Claude on Bedrock
Choose a model when the question is not known in advance. "Does this agreement let us terminate for convenience" is not a field, it is a reading task. The same goes for summaries, comparisons between two versions, and anything where the answer depends on more than one place in the document.
Models also handle formats Textract cannot open. A Word contract, an Excel schedule or a Markdown runbook goes straight into Converse. And when the document already has a text layer, which is true of most PDFs generated by software, a model with citations gives you both the answer and the page it came from.
Amazon Bedrock Knowledge Bases on S3, or just ask the document?
- Ad hoc questions about one file, asked by a person.
- Summaries, comparisons and judgement calls across a document.
- Office formats and text-native PDFs.
- Answers that need a page reference rather than a coordinate.
Chaining them: Textract first, then the model
The common production pattern is both. Textract reads the scan into text and structure, that text goes to the model as a plain-text document, and the model answers questions or classifies the document. This fixes the scan problem for the model and the reasoning problem for Textract, and the Textract output stays available as the audit record. To search across many files as well, the extracted text can be embedded into a vector index in Amazon S3 Vectors.
If the files are text-native PDFs, skip the first step; sending the PDF straight to Converse is cheaper and keeps page citations. If you would rather not wire the pipeline yourself, Amazon Bedrock Data Automation packages extraction and generative output behind one API with S3 input and output, at the cost of another service to learn and price.
Automate S3 file workflows with Python and boto3
- Scans: Textract to text, then the model.
- Text-native PDFs and Office files: straight to the model.
- Keep the Textract JSON as the verifiable record.
Bedrock Data Automation vs Textract
Amazon Bedrock Data Automation (BDA) is the Bedrock-side answer to the pipeline above. It reads a file from S3 and writes JSON back to S3, in two shapes. Standard output is the document broken into pages, elements and words in reading order, with text as Markdown and a normalised bounding box for each element, priced at about $0.010 a page in AWS's own Knowledge Bases example. Custom output is driven by a blueprint, a list of the fields you want, and returns each field with a confidence score and the page it came from, at $0.040 a page for up to 30 fields. Asynchronous jobs take up to 500 MB and 3,000 pages; synchronous calls are limited to 50 MB and 10 pages.
Against Textract, BDA trades geometry for convenience. Textract gives every word a box and a score, has the specialised expense, identity and lending operations, and is the cheapest way to get plain text off a scan at $0.0015 a page. BDA gives you fields with confidence and page numbers without stacking Forms, Tables and Queries at $0.07 a page and then writing a model call on top. Pick BDA when the same fields come out of many known document types and you would otherwise chain Textract and a model yourself; pick Textract when you need raw OCR geometry, the specialised APIs, or the lowest price per page of text. For a person with one question about one file, neither is the right tool; that is the model, or a product built on it.
Amazon Bedrock Data Automation for documents in S3
- Textract: per-word geometry and confidence, specialised expense, ID and lending APIs, $0.0015 to $0.07 a page.
- BDA standard output: layout, text, tables and figures with bounding boxes, about $0.010 a page.
- BDA custom output: blueprint fields with confidence and page number, $0.040 a page up to 30 fields.
- Both are paid per page processed, whether or not anyone reads the result.
Does Amazon Bedrock do OCR?
Not as a service. Bedrock models can describe what is written in an image or a PDF page you send them, but there is no per-word geometry, no confidence score, and Converse citations only work on a document's text layer, so a scanned PDF has nothing to cite. The closest thing to OCR on the Bedrock side is Bedrock Data Automation standard output, which returns text and bounding boxes per page. If the input is paper and you need to know where on the page a value was, Textract is still the tool, and its output can then be handed to a model as plain text.
Where Amazon Q and BucketDesk fit
Neither Textract nor a raw Converse call is something a finance or legal team uses directly. The products people compare at that level are index-based assistants and per-document tools. Amazon Q Business, which indexed S3 buckets behind a chat app, is closed to new customers, and AWS points new work to Amazon Quick, which also crawls and indexes the bucket before it can answer. Both answer across many files and neither extracts fields with coordinates the way Textract does.
Document AI on the features pageAmazon Bedrock data retention modes for business documentsPlans and pricing
BucketDesk Document AI is the per-document route. You open a file in a connected bucket, ask in plain language, and the answer names where in the file it came from, such as the page of a PDF. The model runs on Bedrock in your AWS account, nothing is indexed ahead of time, and BucketDesk keeps the encrypted chat while the file stays in your bucket. It does not replace Textract for bulk extraction; it replaces the script a person would otherwise write to ask one contract one question.
Primary sources
Discussion
0 comments · open to guests · moderatedLiked this? Get the next article by email. No schedule, no digest, one click to leave.