How to restore files from S3 Glacier Flexible Retrieval and Deep Archive
Restore times, prices and commands for S3 Glacier Flexible Retrieval and Deep Archive: pick a retrieval tier, request the restore, check its status, and keep the file before the temporary copy expires.
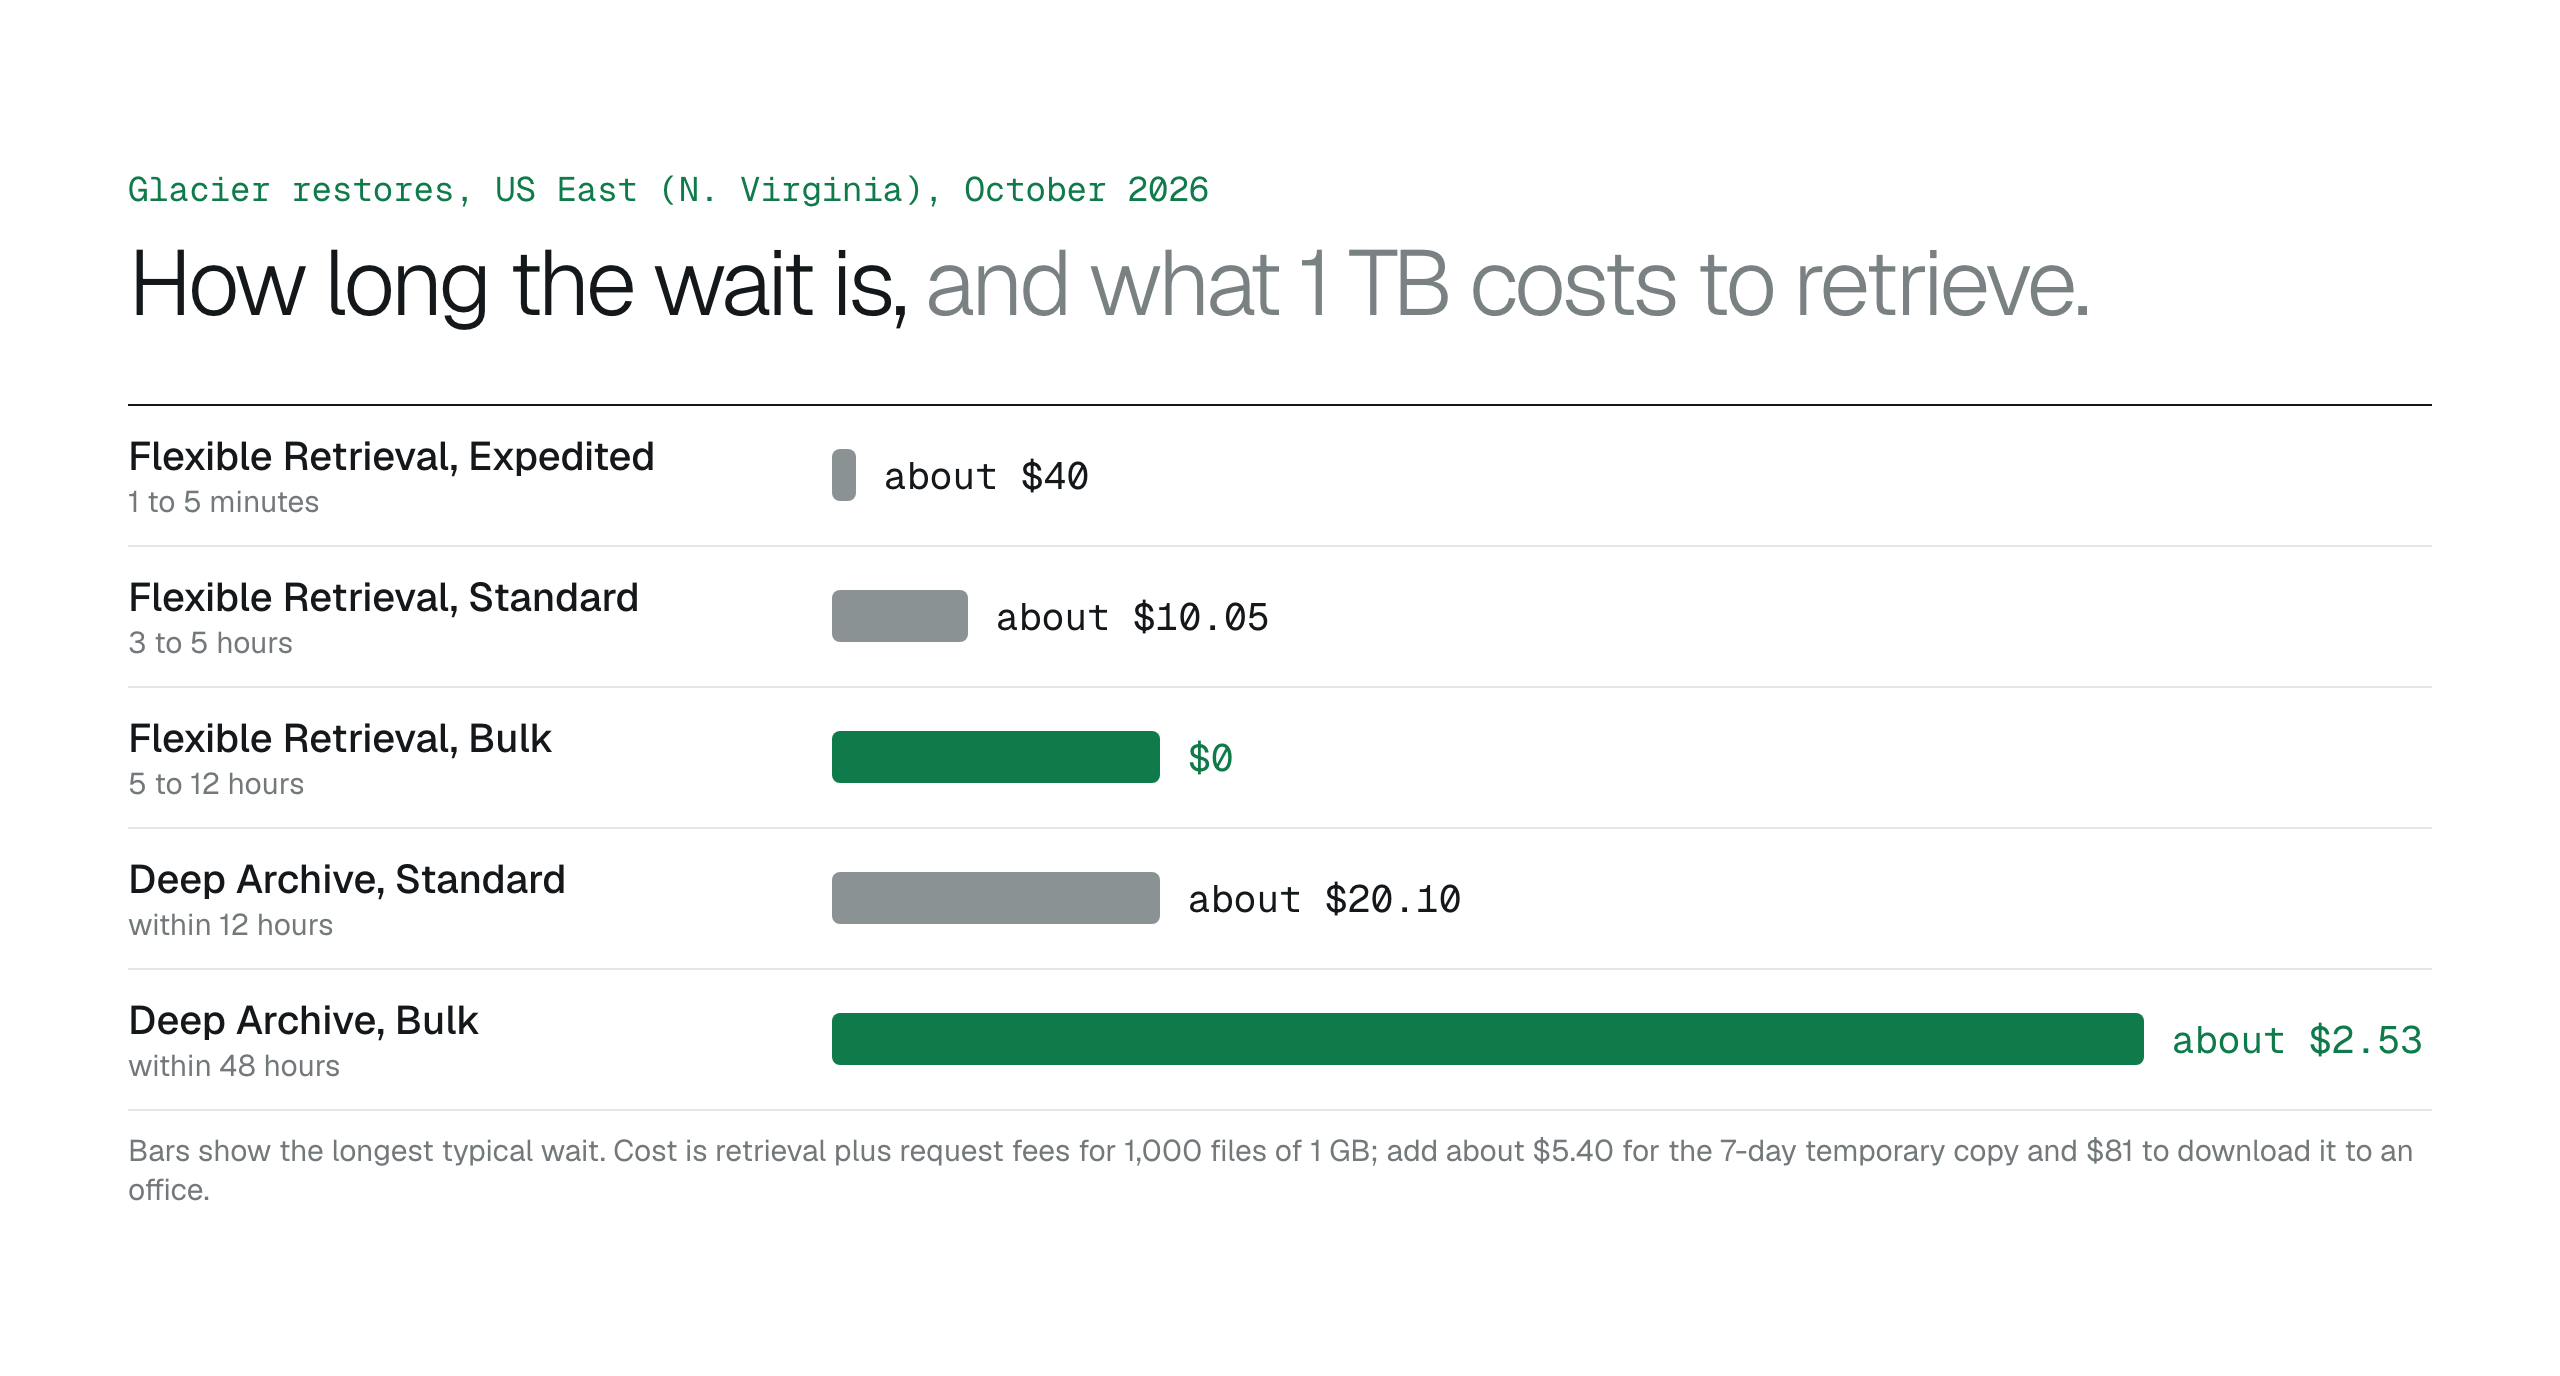
Confirm the storage class first. For Glacier Flexible Retrieval, a restore takes 1 to 5 minutes, 3 to 5 hours or 5 to 12 hours depending on the tier, and Bulk is free; for Deep Archive it takes up to 12 or 48 hours, and 1 TB costs about $2.53 in Bulk or $20.10 in Standard to retrieve. Request it with restore-object, watch the Restore header with head-object, copy the object to a new storage class if access must outlast the restore window, and use Batch Operations for large sets.
To read a file in S3 Glacier Flexible Retrieval or S3 Glacier Deep Archive, you request a restore, wait for it to finish, then read a temporary copy that S3 deletes after the number of days you chose. Flexible Retrieval restores take 1 to 5 minutes (Expedited), 3 to 5 hours (Standard) or 5 to 12 hours (Bulk). Deep Archive restores take up to 12 hours (Standard) or up to 48 hours (Bulk).
The object stays visible in your bucket the whole time; only its contents are unavailable. A restore never changes the object's storage class. To move it out of Glacier for good, you copy the restored object over itself with a new storage class, covered below. Prices in this article are for US East (N. Virginia) as of October 2026.
What is S3 Glacier Flexible Retrieval?
S3 Glacier Flexible Retrieval, GLACIER in the API and the console's older "Glacier" class, is the archive class for files that are read a few times a year and can wait minutes to hours when they are. Storage costs $0.0036 per GB-month in US East (N. Virginia), each object has a 90-day minimum and carries 40 KB of billed overhead (8 KB at the S3 Standard rate, 32 KB at the Glacier rate), and the contents are not readable until you request a restore and choose one of three retrieval tiers: Expedited in minutes, Standard in hours, or Bulk, which is free and takes up to 12 hours.
It sits between the other two Glacier classes. S3 Glacier Instant Retrieval costs more to store, has a 128 KB minimum billable size and a per-GB retrieval fee, but reads in milliseconds with a normal GET, so nothing in this article applies to it. S3 Glacier Deep Archive is cheaper again at $0.00099 per GB-month with a 180-day minimum, but has no Expedited tier and its restores take up to 12 or 48 hours. Flexible Retrieval is the one to pick when an archive occasionally needs to come back the same afternoon.
S3 storage classes: which one for which file
- Flexible Retrieval: $0.0036 per GB-month, 90-day minimum, restores in minutes to 12 hours, Bulk free.
- Instant Retrieval: millisecond reads with a retrieval fee, 90-day minimum, 128 KB minimum billable size.
- Deep Archive: $0.00099 per GB-month, 180-day minimum, restores in 12 to 48 hours.
How long does an S3 Glacier restore take?
These are the typical completion times AWS publishes for each storage class and retrieval tier. Expedited is only available for Flexible Retrieval, and during periods of high demand AWS may refuse Expedited requests unless you have bought provisioned capacity.
Large restores take longer. S3 accepts up to 1,000 restore requests per second per account, restores up to 1 to 2 PB per day per account, and retrieves a single object larger than 5 TB at up to 300 MB per second, so a 50 TB object can take up to 48 hours.
- Flexible Retrieval Expedited: 1 to 5 minutes for objects under 250 MB; larger objects at up to 300 MB per second
- Flexible Retrieval Standard: 3 to 5 hours
- Flexible Retrieval Bulk: 5 to 12 hours
- Deep Archive Standard: within 12 hours
- Deep Archive Bulk: within 48 hours
- With S3 Batch Operations, Standard restores from Flexible Retrieval start within minutes and finish within 5 hours; from Deep Archive they finish in 9 to 12 hours
S3 Glacier Deep Archive retrieval time
Deep Archive has two tiers and no Expedited option: a Standard restore completes within 12 hours and a Bulk restore within 48 hours. That is the whole range, so if a file in Deep Archive might be needed the same day, it is already in the wrong class. Submitted through S3 Batch Operations, Standard restores from Deep Archive finish in 9 to 12 hours. The usual pattern is to request Bulk the evening before for anything that can wait two days, and Standard, at eight times the per-GB price, only when someone is waiting.
Check the storage class before requesting a restore
Look at the object's storage class and restore status. S3 Glacier Instant Retrieval is available through a normal GET request and does not need a restore. S3 Glacier Flexible Retrieval (GLACIER in the API) and S3 Glacier Deep Archive (DEEP_ARCHIVE) require one. The Archive Access and Deep Archive Access tiers of S3 Intelligent-Tiering also require a restore request, but their restored objects move back to the Frequent Access tier instead of using a temporary copy with an expiration date, and their Standard and Bulk restores are free.
If the object is in Instant Retrieval, investigate permissions or the viewing tool before starting a restore. If it is in Flexible Retrieval or Deep Archive, plan for a wait and a limited window to use the restored copy. If the restored files are headed for AI processing, compare Amazon Textract and Claude on Bedrock before the window opens.
How much does an S3 Glacier restore cost?
You pay a fee per GB retrieved and a fee per restore request, then S3 Standard storage ($0.023 per GB-month) for the temporary copy for as many days as you keep it, on top of the archived object. Downloading the restored file to the internet adds data transfer: $0.09 per GB after the first 100 GB each month.
Storage itself costs $0.0036 per GB-month in Flexible Retrieval and $0.00099 in Deep Archive. Deleting or overwriting an object before 90 days in Flexible Retrieval or 180 days in Deep Archive is billed as if it stayed the full period.
- Flexible Retrieval Expedited: $0.03 per GB plus $10.00 per 1,000 requests
- Flexible Retrieval Standard: $0.01 per GB plus $0.05 per 1,000 requests
- Flexible Retrieval Bulk: free
- Deep Archive Standard: $0.02 per GB plus $0.10 per 1,000 requests
- Deep Archive Bulk: $0.0025 per GB plus $0.025 per 1,000 requests
What does it cost to restore 1 TB from Glacier?
Take 1,000 files of 1 GB each (1,000 GB), restored for 7 days. The retrieval fee depends on the tier. The temporary copy adds about $5.40 (1,000 GB at $0.023 per GB-month for 7 days) whichever tier you choose. Downloading all of it to an office adds about $81 of data transfer if it is the only download that month; reading it inside AWS in the same Region does not. Asking an AI model about the files adds its own charge; here is what a Bedrock document question costs.
The cheapest restore is Bulk from Flexible Retrieval, then Bulk from Deep Archive. When nobody is waiting on the file, Bulk is almost always the right tier.
- Flexible Retrieval Expedited: $30 retrieval plus $10 requests, about $40
- Flexible Retrieval Standard: $10 retrieval plus $0.05 requests, about $10.05
- Flexible Retrieval Bulk: $0
- Deep Archive Standard: $20 retrieval plus $0.10 requests, about $20.10
- Deep Archive Bulk: $2.50 retrieval plus $0.025 requests, about $2.53
Request the restore for one object
In the S3 console, select the object, choose Actions, then Initiate restore. Pick the retrieval tier and the number of days the restored copy should remain available. With the AWS CLI, use restore-object and set Days and the tier in GlacierJobParameters. Add --version-id to restore an older version; without it, S3 restores the current version.
Submitting the request does not make the file readable immediately. Sending a second request while the first is running returns a RestoreAlreadyInProgress error, so record which object and version was requested, the tier, the days and who approved the cost. If a lifecycle rule expires the object sooner than the days you asked for, the expiration wins.
aws s3api restore-object --bucket amzn-s3-demo-bucket --key contracts/2019/msa.pdf \
  --restore-request '{"Days":7,"GlacierJobParameters":{"Tier":"Bulk"}}'
How do I check if an S3 restore is complete?
Run head-object on the key and read the Restore field. While the restore runs it shows ongoing-request="true". When it finishes it shows ongoing-request="false" and an expiry-date, which is when S3 deletes the temporary copy. The StorageClass field keeps showing GLACIER or DEEP_ARCHIVE throughout. In the console, the object details page shows Restoration in progress or Restoration complete with the expiry date.
To be told instead of checking, subscribe to the s3:ObjectRestore:Completed event with S3 Event Notifications. If the deadline moves up, the console's Upgrade retrieval tier option switches a running restore to a faster tier. To keep a finished copy longer, send the restore request again with a new Days value; S3 resets the expiry from that moment and charges only for the request.
aws s3api head-object --bucket amzn-s3-demo-bucket --key contracts/2019/msa.pdf
# "Restore": "ongoing-request=\"false\", expiry-date=\"Fri, 23 Oct 2026 00:00:00 GMT\""
Restore or change the storage class?
A restore gives you a temporary readable copy; the object stays archived and keeps being billed at the Glacier rate. If people will open the file regularly, change its storage class instead: restore it first, then copy it over itself with a new storage class before the restored copy expires.
The S3 console can't copy restored Glacier objects, so use the CLI, an SDK or the API. copy-object handles objects up to 5 GB; for larger files use aws s3 cp with the same source and destination, --storage-class STANDARD and --force-glacier-transfer. In a versioned bucket the copy becomes a new current version and the archived version stays as a noncurrent version until a lifecycle rule removes it.
aws s3api copy-object --bucket amzn-s3-demo-bucket --key contracts/2019/msa.pdf \
  --copy-source amzn-s3-demo-bucket/contracts/2019/msa.pdf --storage-class STANDARD
Use Batch Operations when many objects need retrieval
For a collection of archived objects, S3 Batch Operations submits restore requests from a manifest: an S3 Inventory report or a CSV of bucket and key. You choose the tier and the number of days once for the whole job, and it can cover billions of objects. It needs an IAM role that lets S3 restore on your behalf, and an optional completion report lists any object that failed.
Separate jobs are required for Glacier storage-class objects and S3 Intelligent-Tiering archive-tier objects. A single-object request is easier to review when you only need one contract or media file.
Bring the workflow to the people who need the file
BucketDesk Ultra lets an operator restore one Glacier or Deep Archive file, a selection of up to 1,000 or a whole folder from the file workspace, and choose a retrieval tier and how long the copy stays readable. AWS retrieval charges remain in the customer's account.
See BucketDesk storage operations and limitsCompare plansAsk about a pilotSee what your own buckets cost and what each change would save
Primary sources
Discussion
0 comments · open to guests · moderatedLiked this? Get the next article by email. No schedule, no digest, one click to leave.