Amazon Bedrock Knowledge Bases on S3, or just ask the document? Choosing how to chat with business files
What a Bedrock knowledge base adds on top of an S3 bucket, the sync, permission and cost work it brings with it, and the cases where sending one file to Claude is the simpler and safer answer.
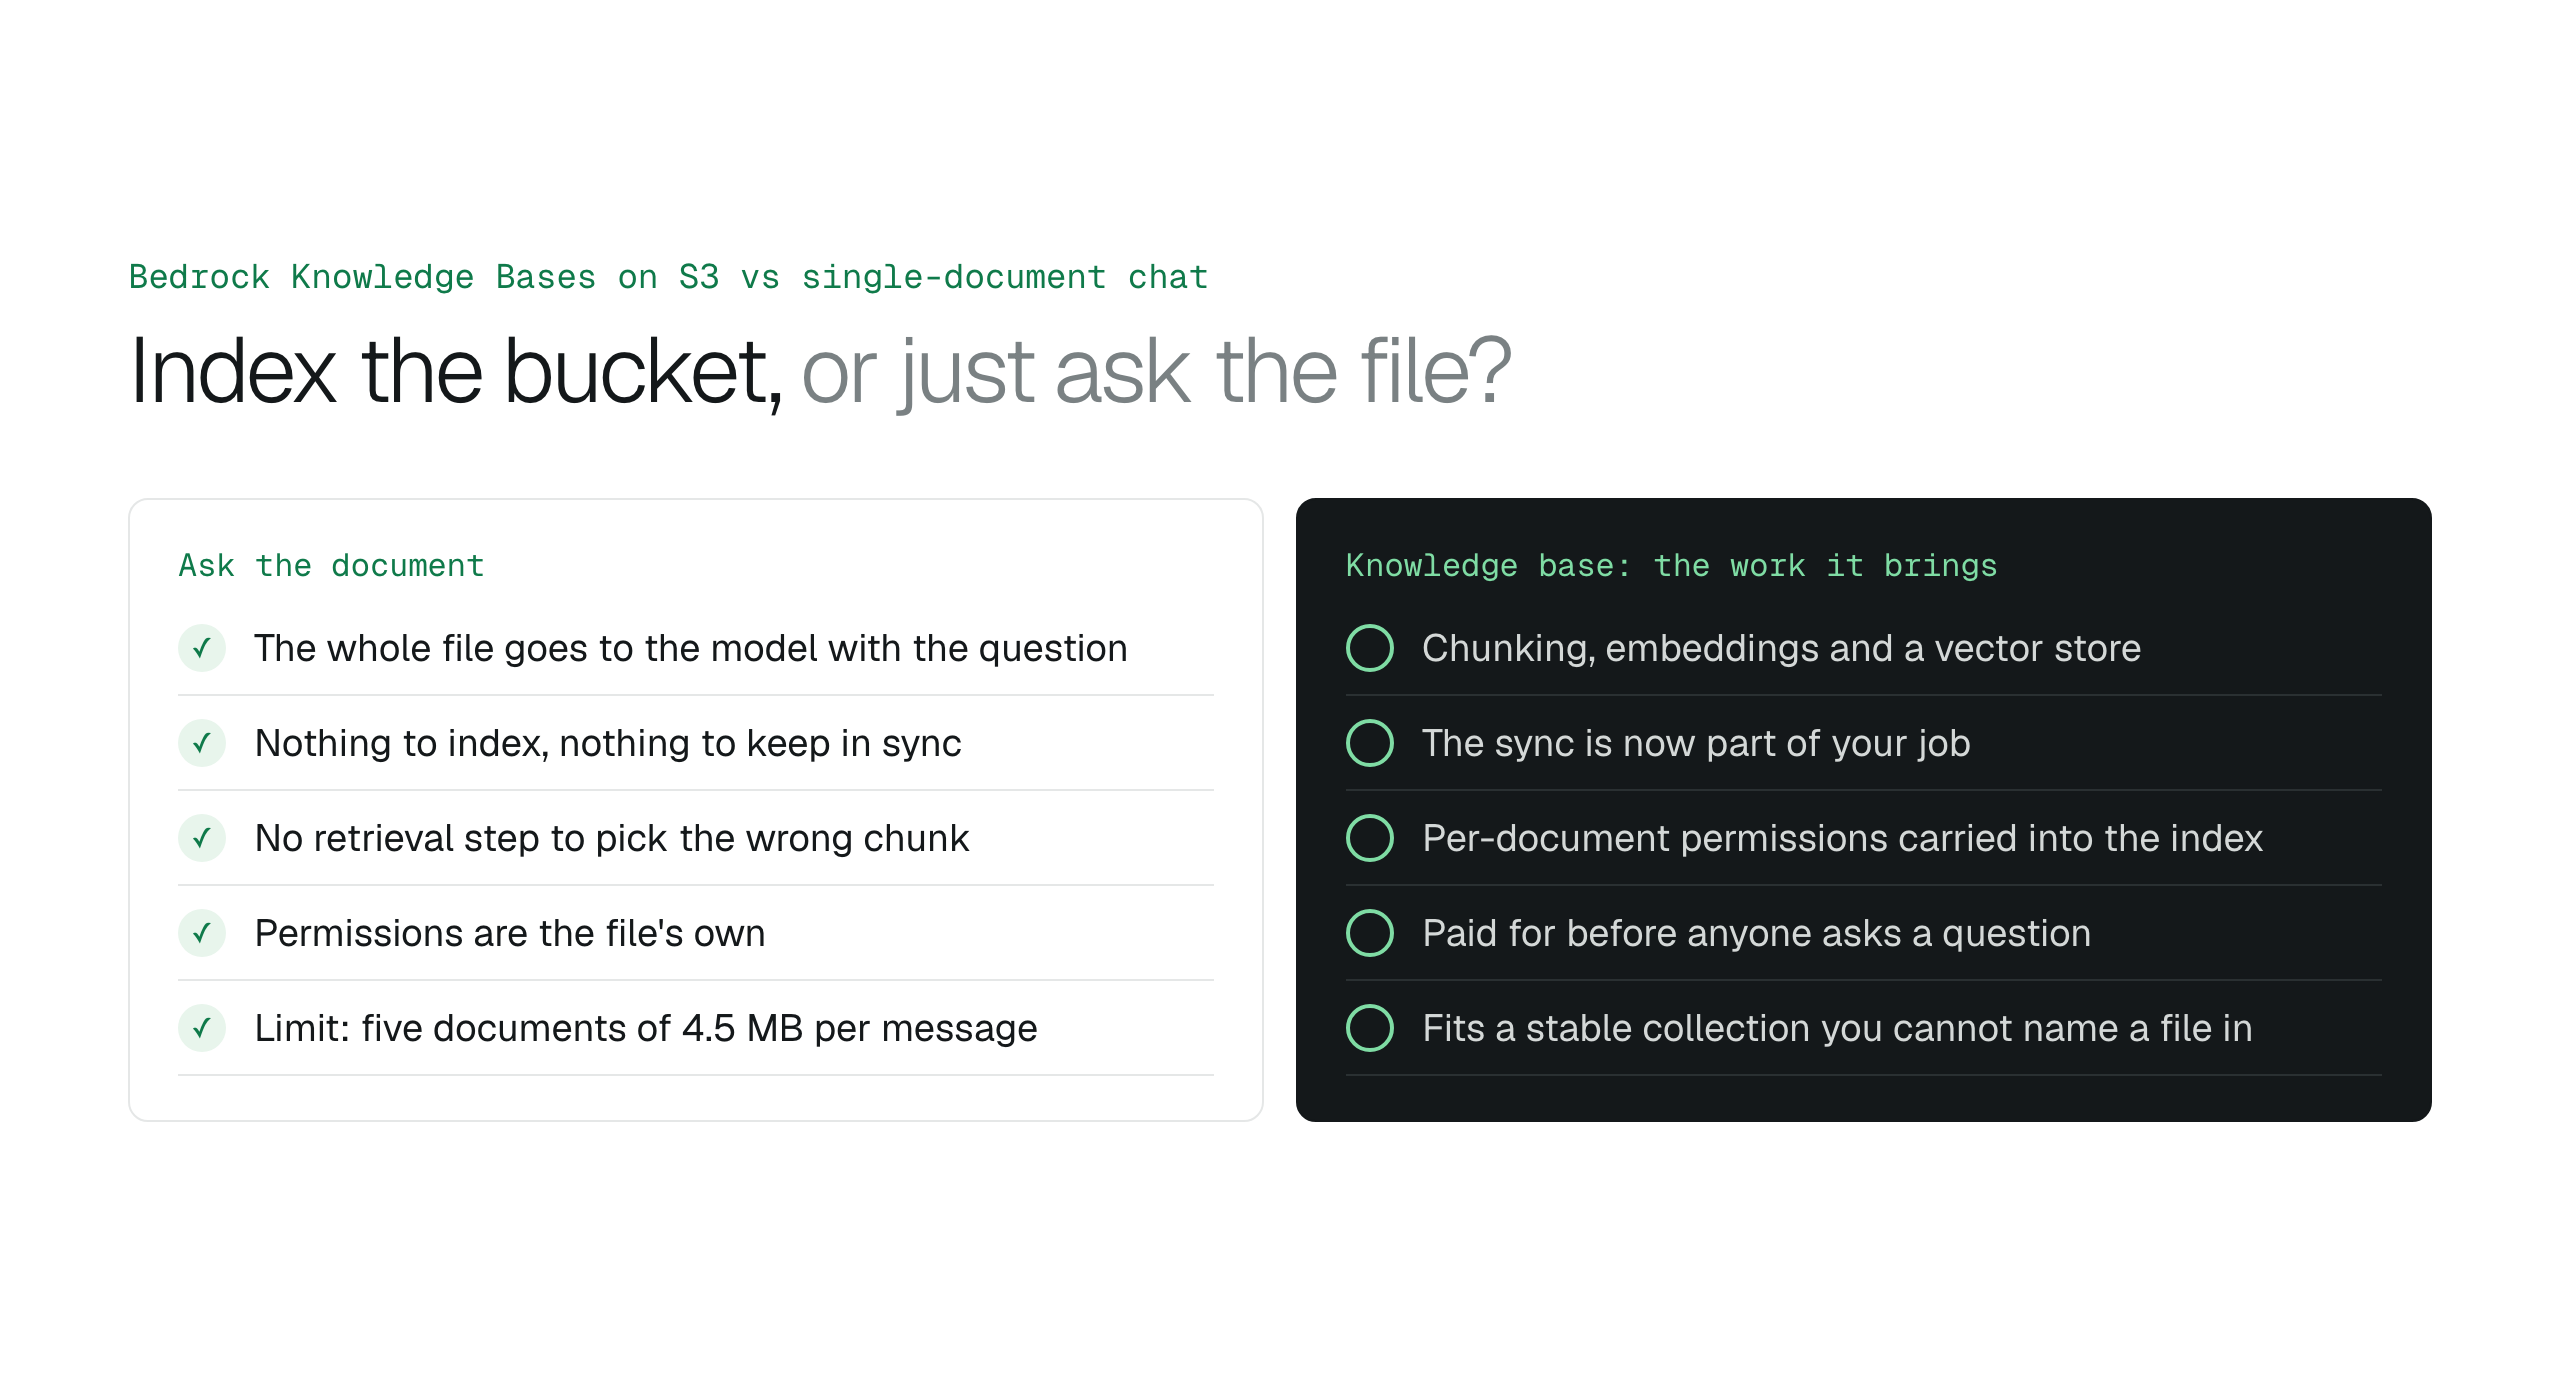
A Bedrock knowledge base is a searchable second copy of your bucket: worth it when people need answers across files they cannot name, at the price of syncs, permission filtering and an always-on index. When the user already has the file open, sending that one document to Claude with citations is simpler, current by definition, and inherits the access the user already has.
"Chat with our documents" can mean two very different systems. One answers a question about the file you have open. The other answers a question about every file in a bucket, which means it first has to find the right files. Amazon Bedrock offers both, and the second, a knowledge base, is getting a lot of attention: searches for Bedrock knowledge bases more than doubled over the past year.
Knowledge bases are the right tool for some jobs. They are also a second copy of your documents, with its own sync, permissions and bill. This article helps you decide before you build one. If you are weighing a broader system for these files, see what content management looks like when files stay in S3.
What a knowledge base does that a single prompt does not
A knowledge base is retrieval augmented generation, RAG, run for you. During ingestion it converts each file in the data source to text, splits it into chunks, turns each chunk into a vector embedding and writes it to a vector index, keeping a pointer back to the source file. At query time it embeds the question, finds the most similar chunks, and hands those chunks to the model to write an answer with citations to the source.
That solves one problem well: the user does not know which file holds the answer. "What is our standard payment term across supplier contracts" cannot be answered by one PDF.
Single-document chat skips all of that. The whole file goes to the model with the question, which means there is nothing to index, nothing to keep in sync, and no chance the retrieval step picked the wrong chunk. The limit is size: the Converse API takes up to five documents of 4.5 MB each per message.
Ask questions about S3 documents with Claude on Amazon Bedrock
Managed or customer-managed knowledge base
Bedrock now offers two kinds. A Managed Knowledge Base runs the ingestion, indexing, storage and retrieval for you. It has connectors for S3, SharePoint, Confluence, Google Drive and OneDrive, parses PDFs, Office files and scanned documents, and can filter results by document-level access control lists at retrieval time. AWS recommends it as the default.
A customer-managed knowledge base gives you the pipeline: you choose and run the vector store, such as OpenSearch Serverless, Aurora or Neptune, and control parsing and chunking. Third-party connectors, document-level permissions and AgentCore Gateway integration are only available on the managed kind.
- Managed: less to run, document-level permission filtering, AWS-chosen models by default.
- Customer-managed: full control of chunking and the vector store, and you operate it.
The sync is now part of your job
A knowledge base does not watch the bucket. Each time files are added, changed or removed, the data source has to be synced, through the console or a StartIngestionJob call. Sync is incremental: unchanged files are skipped, changed ones are re-parsed, re-chunked and re-embedded, and deleted files are removed from the vector store.
Until the next sync completes, answers come from the old copy. That is fine for a policy library updated monthly and a real problem for a contracts folder where a revised draft lands every afternoon. Plan the trigger, usually an S3 event or a schedule, and watch the job status.
aws bedrock-agent start-ingestion-job \
  --knowledge-base-id KB12345678 \
  --data-source-id DS12345678

aws bedrock-agent list-ingestion-jobs \
  --knowledge-base-id KB12345678 \
  --data-source-id DS12345678 \
  --max-results 5
Permissions are the hard part
In S3, who can read a file is decided by IAM and bucket policies at the moment they ask. In a knowledge base, the text of every ingested file sits in one index, and the question is answered by whoever the application calls Bedrock as. If finance and HR documents share an index and the application does not filter, an HR question can be answered with a finance passage.
Managed knowledge bases can apply document-level ACLs from supported connectors at retrieval time. With a customer-managed one you typically attach metadata to each file with a matching .metadata.json object and filter on it per request. Either way, test it with a user who should not see a document before you trust it.
S3 bucket policy examples for team file accessIs Amazon S3 secure for business documents?
Cost: what you pay for before anyone asks a question
Single-document chat costs model tokens per question and nothing in between. A knowledge base adds embedding every chunk at ingestion and again on every change, plus the vector store, which for a customer-managed setup runs whether or not anyone is asking. A knowledge base over a large archive that is queried a few times a month can cost more to keep than to use.
Inside BucketDesk: the AWS architecture behind your file workspaceAmazon S3 pricing and costs, charge by charge
A quick way to decide
Start from the question your team actually asks. If they already know which file they mean, which is most questions about a contract, an invoice or a report, ask the document. If the question spans files they cannot name, and the collection is stable enough to keep in sync, a knowledge base earns its keep.
BucketDesk's Document AI is deliberately the first kind: open a file in your bucket from the dashboard, ask, and get an answer that names where in the file it came from, scoped to that one file and run through Amazon Bedrock in your AWS account, reached with a scoped IAM role and External ID. Nothing is indexed ahead of time, and chats are kept encrypted and deleted 30 days after they end. Document agents with bounded actions are on the roadmap.
Document AI on the features page
- Ask the document: you know the file, it changes often, or permissions vary file by file.
- Knowledge base: you do not know the file, the collection is stable, and permissions are uniform or filterable.
Chat with the file you already have open
BucketDesk Document AI sends the one document a person has open to a model on Amazon Bedrock in your own AWS account and answers with citations. Every answer reflects the current file, and people ask only about files their workspace access already lets them open.
Ask questions about S3 documents with Claude on Amazon BedrockPlans and pricing
Document AI is part of the Ultra plan, which is free for one month.
Primary sources
Discussion
0 comments · open to guests · moderatedLiked this? Get the next article by email. No schedule, no digest, one click to leave.