S3 file viewer guide, how to view files in Amazon S3 in your browser and which viewer to choose
Which files in Amazon S3 open in a browser and which download, why Content-Type and Content-Disposition decide it, how to view an object with the console or a presigned URL, and what to check before you give a team an S3 viewer.
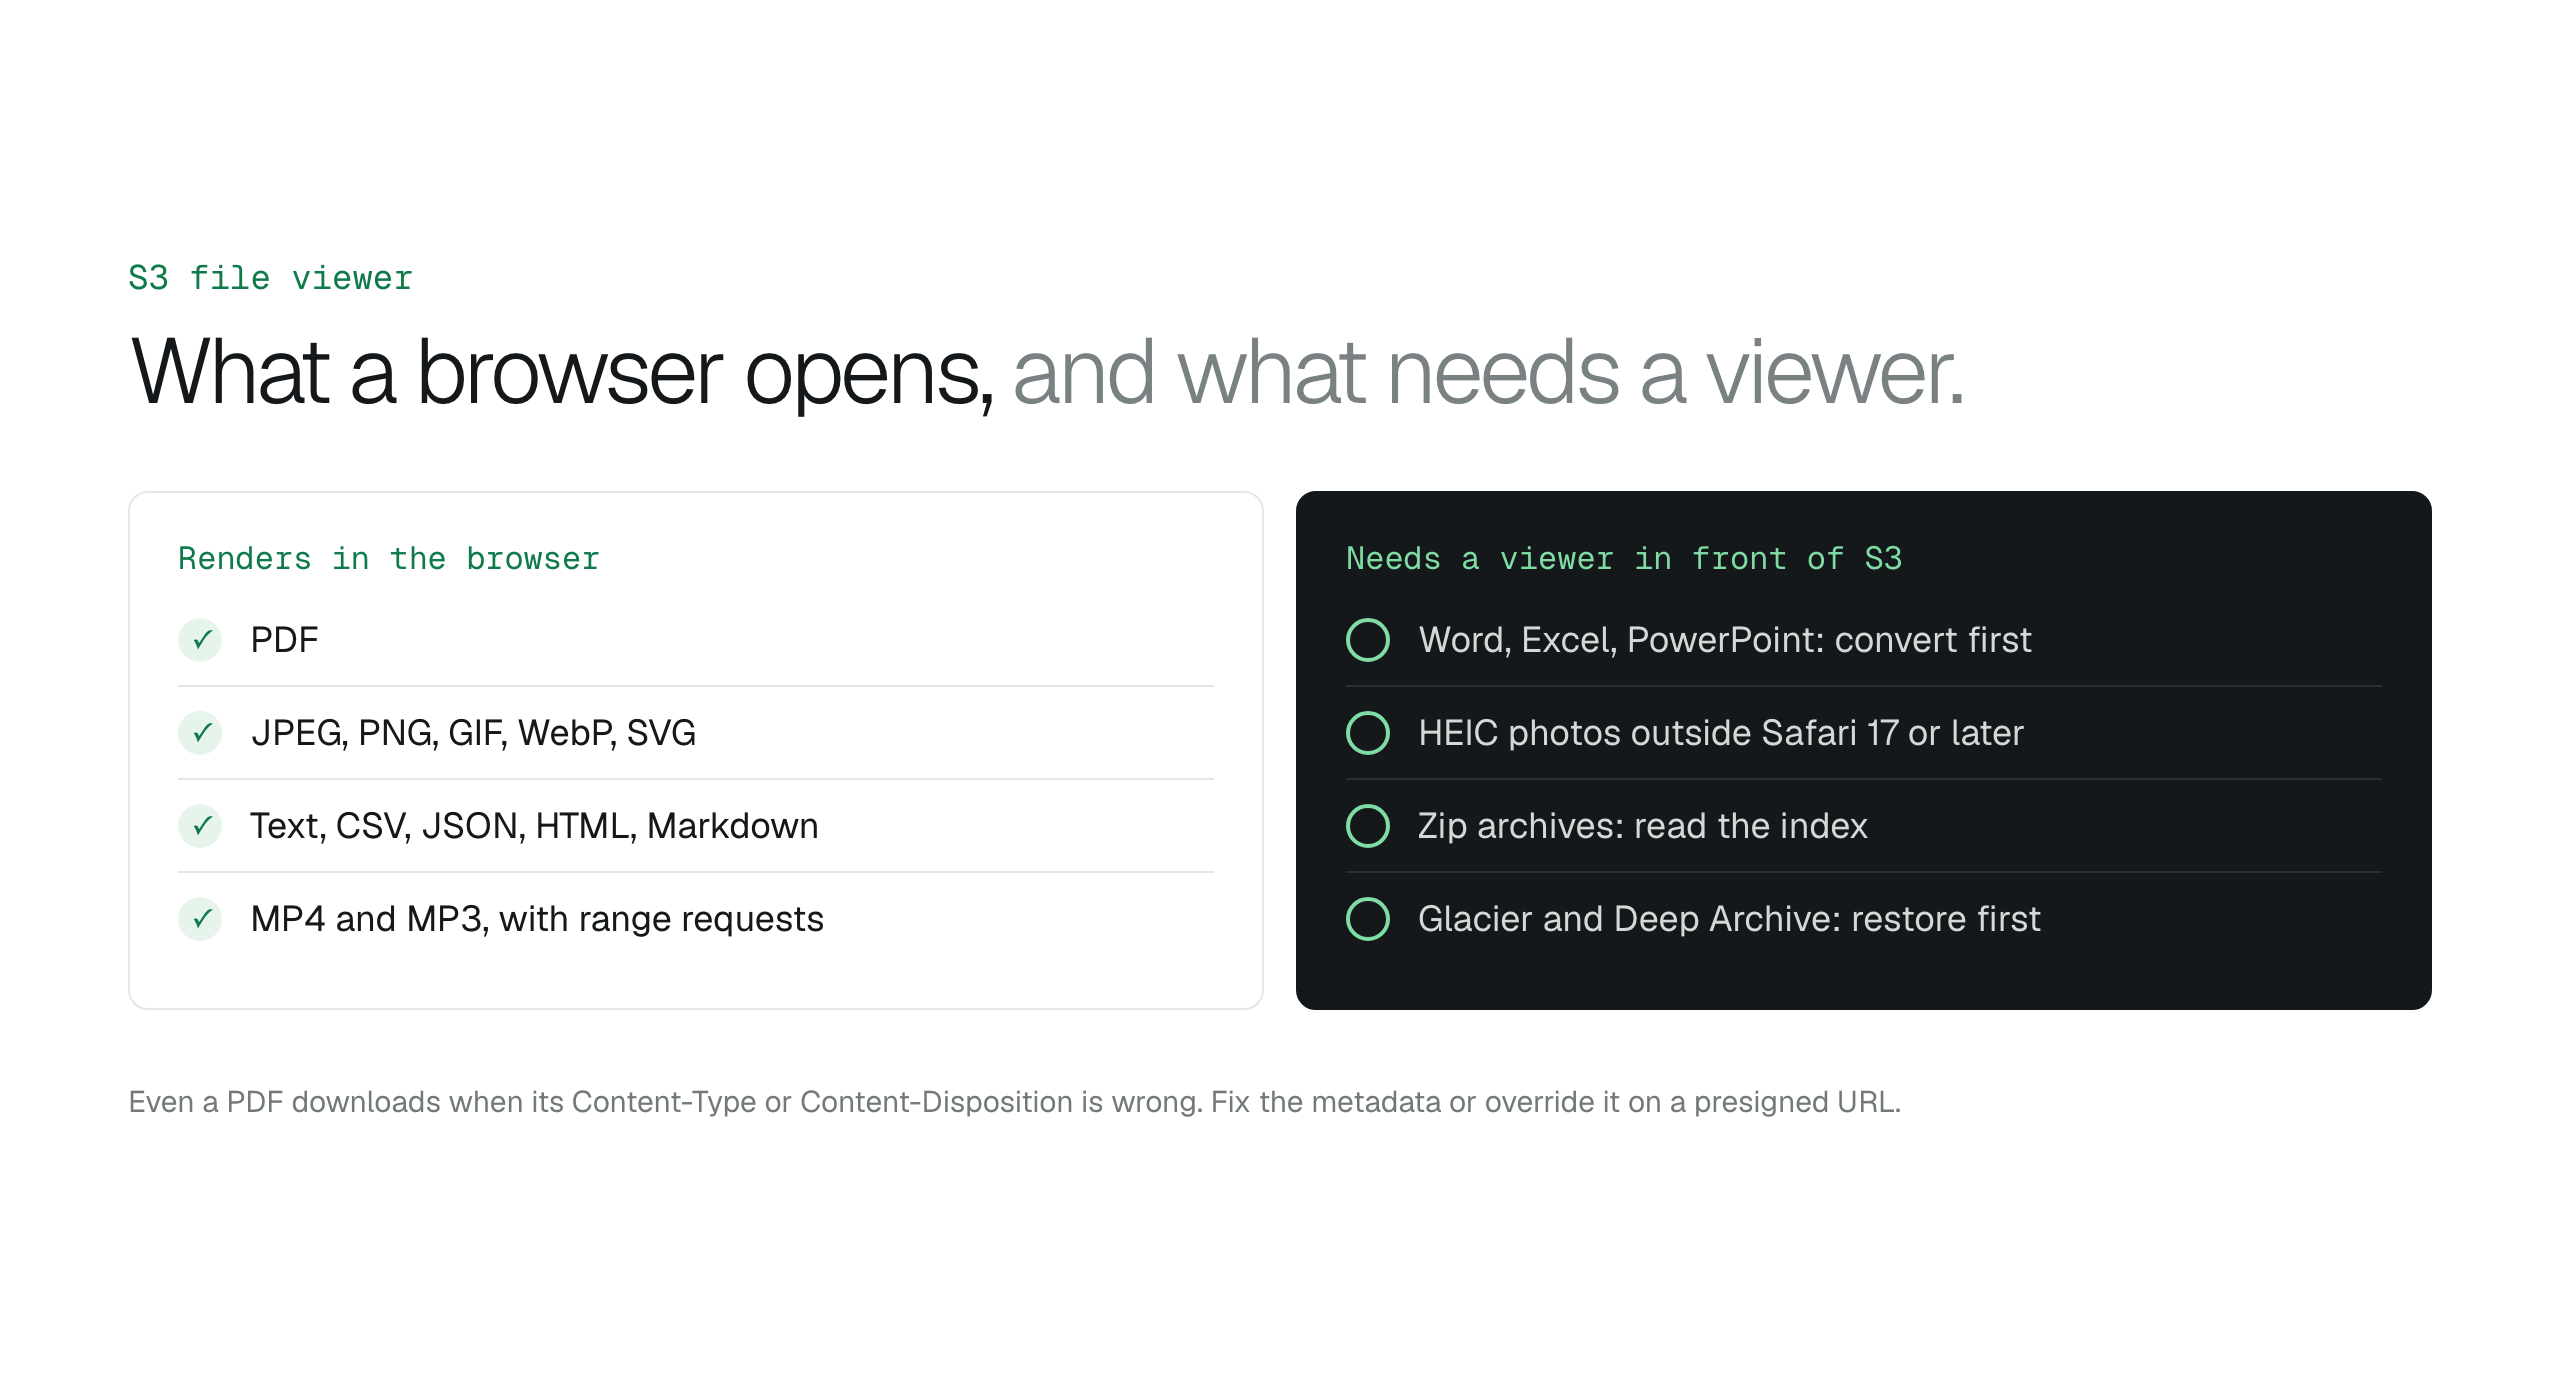
For one file, fix its Content-Type and Content-Disposition or open it with a presigned URL. For a team that opens Office files, HEIC photos, media and archives from S3, use a viewer that renders them in the browser, and judge it on how it is granted access, where contents travel and what it records.
An S3 file viewer opens an object from an Amazon S3 bucket in the browser instead of saving it to disk. For a single PDF, image or text file, the S3 console or a presigned URL works as long as the object has the right Content-Type; Word, Excel, PowerPoint, HEIC photos and archives need a viewer that converts or reads them for you.
This guide covers which files open how, the header fixes that turn a download into a preview, and the questions to ask before giving a team a browser-based S3 viewer.
Why some S3 files open and others download
A browser decides what to do with a file from two response headers. Content-Type tells it what the bytes are. Content-Disposition tells it whether to show them inline or save them as an attachment. S3 returns both from the object's metadata, which is set when the object is uploaded.
Scripts and backup tools often upload with a generic type such as binary/octet-stream, so the browser has nothing to render and saves the file. An object stored with Content-Disposition set to attachment downloads even when its type is correct. You can fix the stored metadata by copying the object onto itself with new headers, which replaces the metadata without changing the bytes. REPLACE drops any custom metadata the object had, so pass it again with --metadata if you need it.
aws s3 cp s3://my-bucket/contracts/msa.pdf s3://my-bucket/contracts/msa.pdf \
  --content-type application/pdf --content-disposition inline \
  --metadata-directive REPLACE
Which file types can a browser show?
Even with correct headers, a browser only renders formats it understands. Everything else needs a converter or a dedicated player in front of S3.
- PDF: renders in every current desktop browser.
- Images: JPEG, PNG, GIF, WebP and SVG render natively. HEIC photos from iPhones render only in Safari 17 or later; Chrome, Edge and Firefox need a converted copy.
- Text, CSV, JSON, HTML and Markdown: show as text, or as a web page for HTML.
- Audio and video: common formats such as MP4 and MP3 play in the tab, and large files need range requests so playback can start before the whole file arrives.
- Word, Excel and PowerPoint: browsers cannot display them; a rendering service has to convert them first.
- Visio diagrams: browsers cannot display .vsdx files; see how to choose a Visio viewer.
- Zip and other archives: a browser can only download them; listing what is inside needs a tool that reads the archive index.
- Objects in S3 Glacier Flexible Retrieval or Deep Archive: cannot be read at all until a restore completes.
How do I view a file in S3 without downloading it?
In the S3 console, open the bucket, choose the object and use Open on its details page to view it in a new tab. The browser then applies the rules above, so a correctly typed PDF displays and a mislabelled one downloads.
For someone without console access, create a presigned URL. It grants time-limited access to one object with the permissions of whoever signed it, up to 12 hours when created in the console. A presigned URL generated with an SDK can also override the stored headers for that one response with the response-content-type and response-content-disposition parameters, so a mislabelled PDF opens inline without touching the object. These overrides only work on signed requests, and anyone holding the URL can open the object until it expires.
Your S3 viewer options
Which one fits depends on who is looking and what they open. For one engineer checking a PDF, the console is enough. For a team opening contracts, spreadsheets, decks and media every day, the gaps in the list above add up.
S3 file browser options comparedWhen Storage Browser for Amazon S3 is the better choice
- The S3 console: included with AWS and good for one-off checks, but every viewer needs an IAM identity and it shows only what the browser can render.
- Presigned URLs: good for sending one file to one person, but each link is a bearer token with no record of who opened it.
- Desktop clients such as Cyberduck, CS Browser and Transmit: built for transfers; files open in whatever the computer has installed after they download.
- Storage Browser for Amazon S3: an AWS React component for list, upload, download, copy and delete inside your own app; previews are yours to build.
- A hosted workspace such as BucketDesk: renders PDFs, images, Office files and media in the browser on top of your bucket, connected by an IAM role.
How does the viewer get access to the bucket?
A viewer that asks for an access key and secret is asking you to hand over a long-lived credential. The better pattern is a cross-account IAM role with an external ID, scoped to specific buckets and prefixes, that the vendor assumes for short-lived credentials. You can see exactly what was granted, and you can revoke it by deleting the role.
Where do the file contents go?
A desktop client reads straight from S3 to the laptop. A hosted viewer reads the object on your behalf. Ask whether contents are cached, for how long, and whether any third party is involved in rendering. A trustworthy answer names the exceptions, such as Office conversion, and says where each one happens.
Who can do what, and is it recorded?
- Separate viewing from changing. Most people only need to read.
- Risky actions such as delete, extract and restore should require a specific role and a confirmation.
- Every open, share and change should be attributable to a signed-in person, and exportable.
An S3 file viewer for the whole team
BucketDesk is a browser workspace that connects to your bucket through a scoped IAM role and renders files in the browser. Files are read by range straight from your bucket. Word, Excel and PowerPoint are converted on BucketDesk's own document server, which fetches the file with a short-lived link and keeps it only while the document is open.
- Open the file
PDF, images including HEIC, text, HTML and Markdown preview on every plan.
- Open Office and media
Word, Excel and PowerPoint previews and streamed audio and video on Standard and Ultra.
- Look inside archives
inspect a zip before anything is extracted, on Standard and Ultra.
See the S3 web browser for teamsSee every feature with its plan and limitsPlans and pricingCompare these steps with the AWS Console
Minimum is free for one bucket and one viewer. Standard is $100 a month and adds Office previews, media streaming, expiring shares, archive operations, five operators and unlimited viewers. Ultra is $350 a month with a one-month free trial, and adds questions answered from one open document with a citation to the page or section, uploads, and restore from Glacier and Deep Archive.
Primary sources
- AWS: Downloading objects (console and presigned URLs) ↗
- AWS: GetObject API reference (response header overrides and Range) ↗
- AWS: Working with object metadata ↗
- AWS CLI: s3 cp ↗
- Can I use: HEIF/HEIC image format ↗
- AWS: Working with Storage Browser for Amazon S3 ↗
- AWS: The confused deputy problem and external IDs ↗
- AWS: Security best practices in IAM ↗
Discussion
0 comments · open to guests · moderatedLiked this? Get the next article by email. No schedule, no digest, one click to leave.