Enterprise content management when the content already lives in Amazon S3
AWS enterprise content management starts with Amazon S3, which already covers storage, versions, retention, encryption and audit. Here is that half, the half S3 leaves to you, and the AWS services and products that fill it.
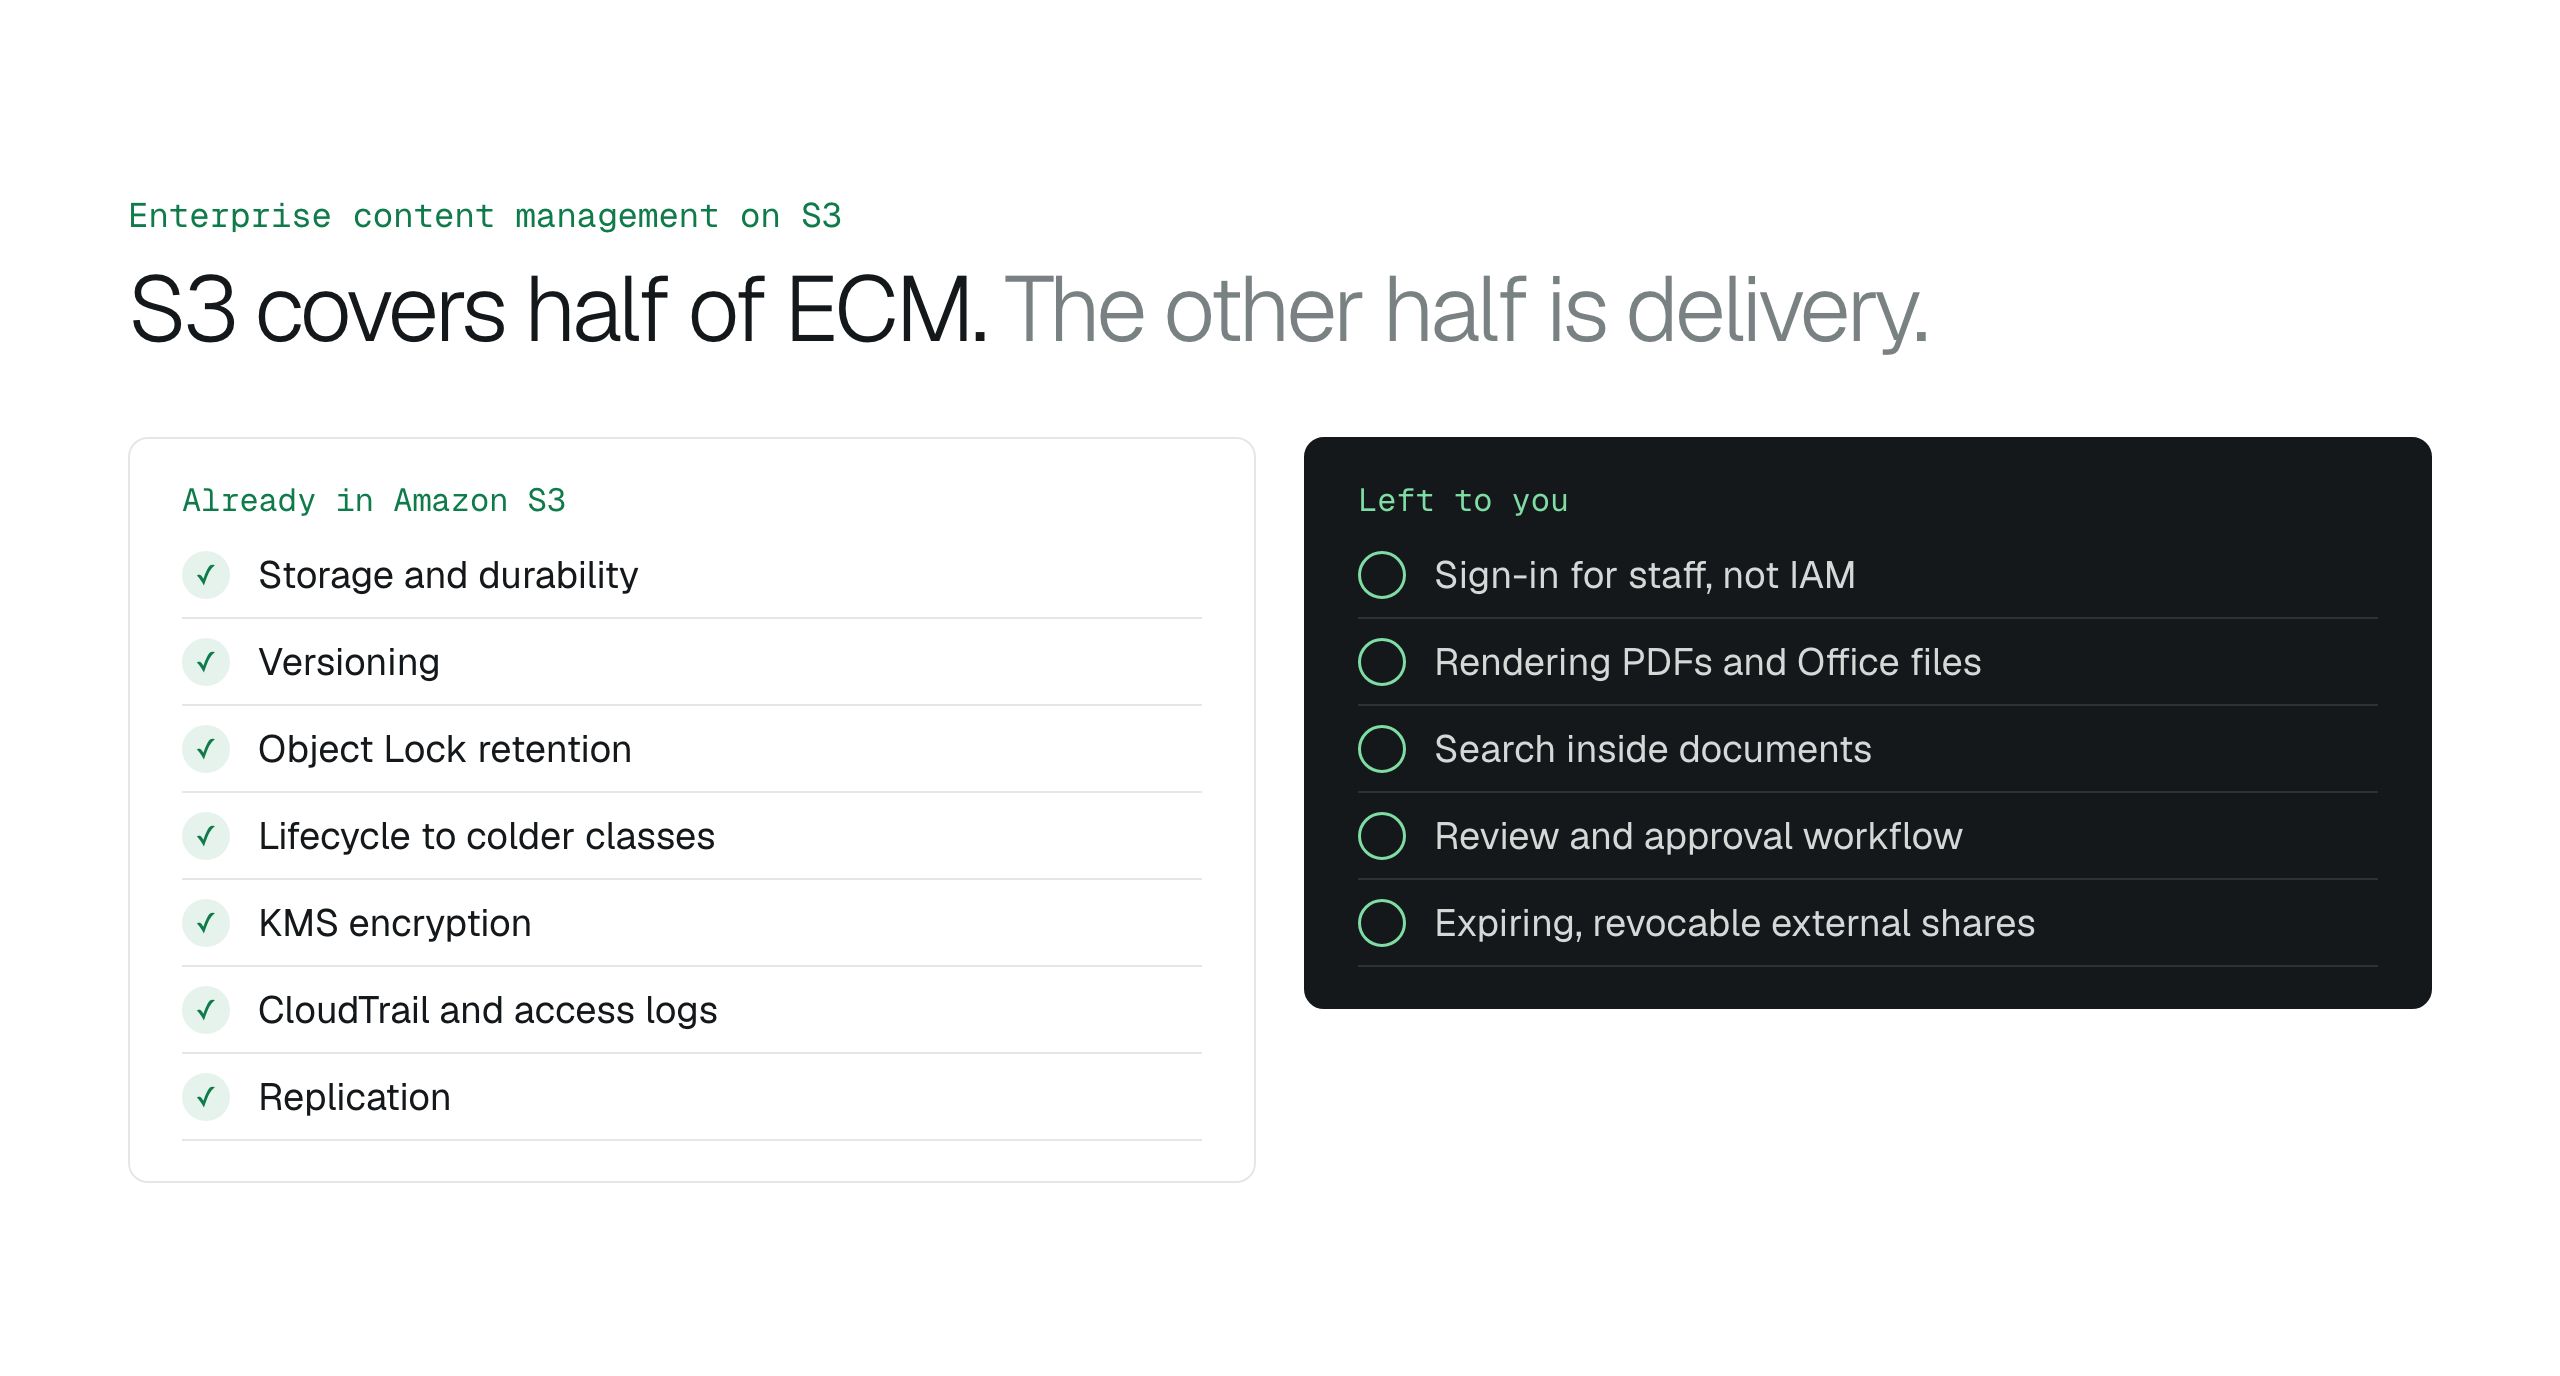
For AWS enterprise content management, Amazon S3 already covers the storage, versioning, retention and audit half. What it does not cover is people: identity, previews, searchable business metadata, sharing and approvals. Work out which half you are actually missing before you decide whether to move a single file.
Enterprise content management on AWS is built on Amazon S3: S3 Versioning, Object Lock, lifecycle rules, KMS encryption and CloudTrail cover the store, preserve and audit half of ECM. The other half, which is sign-in for staff, previews, metadata search, external sharing and workflow, has to come from AWS services you assemble, an ECM platform you move content into, or a workspace that runs on your buckets.
Enterprise content management is usually sold as a destination: move your documents into a platform, and the platform takes care of retention, permissions, search and audit. If your files are already in Amazon S3, that framing is backwards. You do not have a content problem waiting for a platform. You have a storage layer that already does about half of what ECM means, and a gap where the other half should be.
This guide separates the two. It works through the jobs an ECM system is expected to do, names the Amazon S3 feature that covers each one, and is explicit about the jobs S3 leaves entirely to you. Every S3 capability referenced here links to its AWS documentation at the end.
What enterprise content management actually covers
ECM is an umbrella over five jobs: capture content, store it durably, manage it while it is in use, preserve it for as long as a rule says you must, and deliver it to the people who need it. Vendors bundle these differently, and a feature grid rarely distinguishes between the rows that are genuinely hard and the rows that are a checkbox.
Digital asset management gets listed beside ECM and is not the same job. DAM is built around rich media: renditions, derivative formats, usage rights and creative review. ECM is built around documents and records: versions, approvals, retention schedules and defensible disposal. A team that mostly stores photography and video needs the first. A team that stores contracts, invoices and board papers needs the second. Buying the wrong one is how an organisation ends up with an elegant asset browser that cannot answer a legal hold.
- Capture: getting content in, with enough metadata that it can be found again.
- Store: durable storage with a cost model you can live with for a decade.
- Manage: versions, permissions, and a record of who changed what.
- Preserve: retention rules, legal holds, and disposal you can defend.
- Deliver: getting the right file to the right person in a form they can read.
The half Amazon S3 already gives you
Store and preserve have direct S3 answers, and they are the expensive halves to build. Durability and scale are the product itself: S3 holds as many objects as you want, each up to 50 TB, with the true ceiling set by the multipart limits at 48.8 TiB. S3 Versioning keeps every revision of a key, including delete markers, so an overwrite or an accidental delete is recoverable rather than final.
S3 Object Lock is the feature that turns a retention policy from a promise into an enforced rule. It applies write-once-read-many protection in governance or compliance mode for a retention period, plus a legal hold that stays in force until someone with the right permission explicitly removes it. Lifecycle rules handle the cost half of preservation: transition objects to colder storage classes on a schedule, and expire them when the schedule says their time is up.
The audit rows fill in the same way. Server-side encryption with an AWS KMS key gives you a key you control and a trail of its use. CloudTrail data events and S3 server access logs record object-level activity. Replication copies objects to another bucket or Region for resilience or data residency. Read that list against an ECM feature grid and most of the storage, preservation and durability rows are already ticked, by a service your organisation is very likely already paying for.
The half S3 does not do at all
The gap is delivery, and it is where S3-based content efforts stall. S3 has no concept of a person. It has principals, policies and keys. There is no sign-in page for a contracts manager, no way to express "the legal team can read this prefix" without someone writing IAM, and no rendering: a GetObject returns bytes, and whether those bytes open in a browser or land in a downloads folder depends on the content type that happened to be set when the object was written.
Capture has the mirror-image gap. The metadata a business team would search by, such as client, matter number, effective date or status, has to be attached as object tags or user-defined metadata by whatever put the object there. S3 gives you no interface for maintaining it. S3 Metadata can keep read-only tables of system metadata, tags and user-defined metadata that you query in SQL with Amazon Athena, which helps engineers and auditors, but it is a query service rather than a search screen for staff. Listing is by key prefix, which means your naming convention is your filing system. There is no index of file contents, and S3 Select, which once offered limited in-object querying, is no longer available to new customers.
- No end-user identity: access means IAM principals, not staff accounts.
- No rendering: PDFs, Office files and media are bytes until something converts them.
- No content search: listing is prefix-based, with no index of what is inside a file.
- No workflow: nothing routes a document for review or records an approval.
- No external share that expires, can be revoked, and names who opened it.
Three ways to close the gap
One way is to build the delivery layer from AWS parts. Storage Browser for S3 is an open source React component, part of AWS Amplify, that lets authorized users browse, upload, download, copy and delete objects from inside your own web application. Amazon Bedrock Knowledge Bases or Amazon Quick can index an S3 bucket so people can ask questions across its documents, and Amazon Q Business, the older option, is no longer open to new customers. This route gives full control and needs developers to build and maintain it. If people mostly ask about one file at a time, weigh a knowledge base against asking one document.
The second way is to move the content into an ECM or document platform and let it own storage as well. You get the whole feature grid on day one, and you accept that your records now live in a vendor account, under their limits, their pricing model and their export process. For plenty of organisations that trade is obviously correct, particularly where the content is created inside the same suite that will manage it.
The third way is to keep S3 as the system of record and add a ready-made delivery layer: sign-in, roles, previews, expiring shares and an activity record, reading from the bucket you already own. Retention, versioning, encryption and lifecycle stay where they are and keep applying to every other system that touches the bucket, including the data pipeline, the backup job and the application that writes there. Nothing has to be migrated, and nothing has to be migrated back.
The third route is the one to check carefully, because the questions that matter are about the access layer rather than the feature list. Ask how the product reaches your bucket, whether file contents are stored anywhere outside your account, which formats genuinely render in a browser, and what is written to an activity log when someone opens or shares a document.
S3 document management: what S3 does and what to addCloud document management software for your own storageHow to evaluate a browser-based S3 viewerAmazon Quick Suite for S3 documents
A short evaluation checklist
- Which of the five jobs do you actually have a problem with today? If it is delivery, do not buy storage.
- Is anything legally required to be retained? Configure Object Lock on the bucket before choosing a product, not after.
- What do people need to search by, and does that metadata exist on the objects yet? If not, no tool can search it.
- Who needs access without an AWS identity, and what would you have to hand them today to make that work?
- If the tool went away next year, where would your content be? With S3 as the system of record, the answer does not change.
Where BucketDesk sits in that picture
BucketDesk is the third route: a workspace over S3 buckets you continue to own. It connects through a scoped IAM role deployed with CloudFormation in your own account and assumed for short-lived credentials that expire on their own. People sign in to BucketDesk rather than to the AWS console, and every action lands in Activity.
- Deliver
browse prefixes as folders and preview PDFs, images and text in the browser, with Word, Excel, PowerPoint and media on Standard.
- Share
send expiring, revocable links that ask the recipient for a six-digit code sent to their email and record every open, on Standard and Ultra.
- Ask
on Ultra, ask questions about one open document and get answers that cite the passage.
Review features and plan limitsCompare plansCompare these steps with the AWS Console
Minimum is free for one bucket. Standard is $100 a month and adds every bucket, five operators, unlimited viewers, Office previews and expiring shares. Ultra is $350 a month, with a one-month free trial, and adds uploads, Document AI and manual restores from deep storage. Workflow, records declaration and full-text search across a bucket need other tools, and retention and disposal stay as S3 settings on the bucket.
Primary sources
- AWS: Amazon S3 objects overview ↗
- AWS: Retaining multiple versions of objects with S3 Versioning ↗
- AWS: Locking objects with S3 Object Lock ↗
- AWS: Managing the lifecycle of objects ↗
- AWS: Using server-side encryption with AWS KMS keys ↗
- AWS: Logging Amazon S3 API calls with AWS CloudTrail ↗
- AWS: Filtering and retrieving data with Amazon S3 Select ↗
- AWS: Discovering your data with S3 Metadata tables ↗
- AWS: Working with Storage Browser for Amazon S3 ↗
- AWS: Connect to Amazon S3 for your Bedrock knowledge base ↗
- AWS: Amazon S3 integration in Amazon Quick ↗
- AWS: Amazon Q Business availability change ↗
Discussion
0 comments · open to guests · moderatedLiked this? Get the next article by email. No schedule, no digest, one click to leave.