Cloud document management software when the files are already in your own cloud storage
Pick cloud document management software by whose account holds the file. Here is what to check when your documents already live in S3, Azure or Google Cloud Storage, and the trade-off between tools that copy files and tools that work in place.
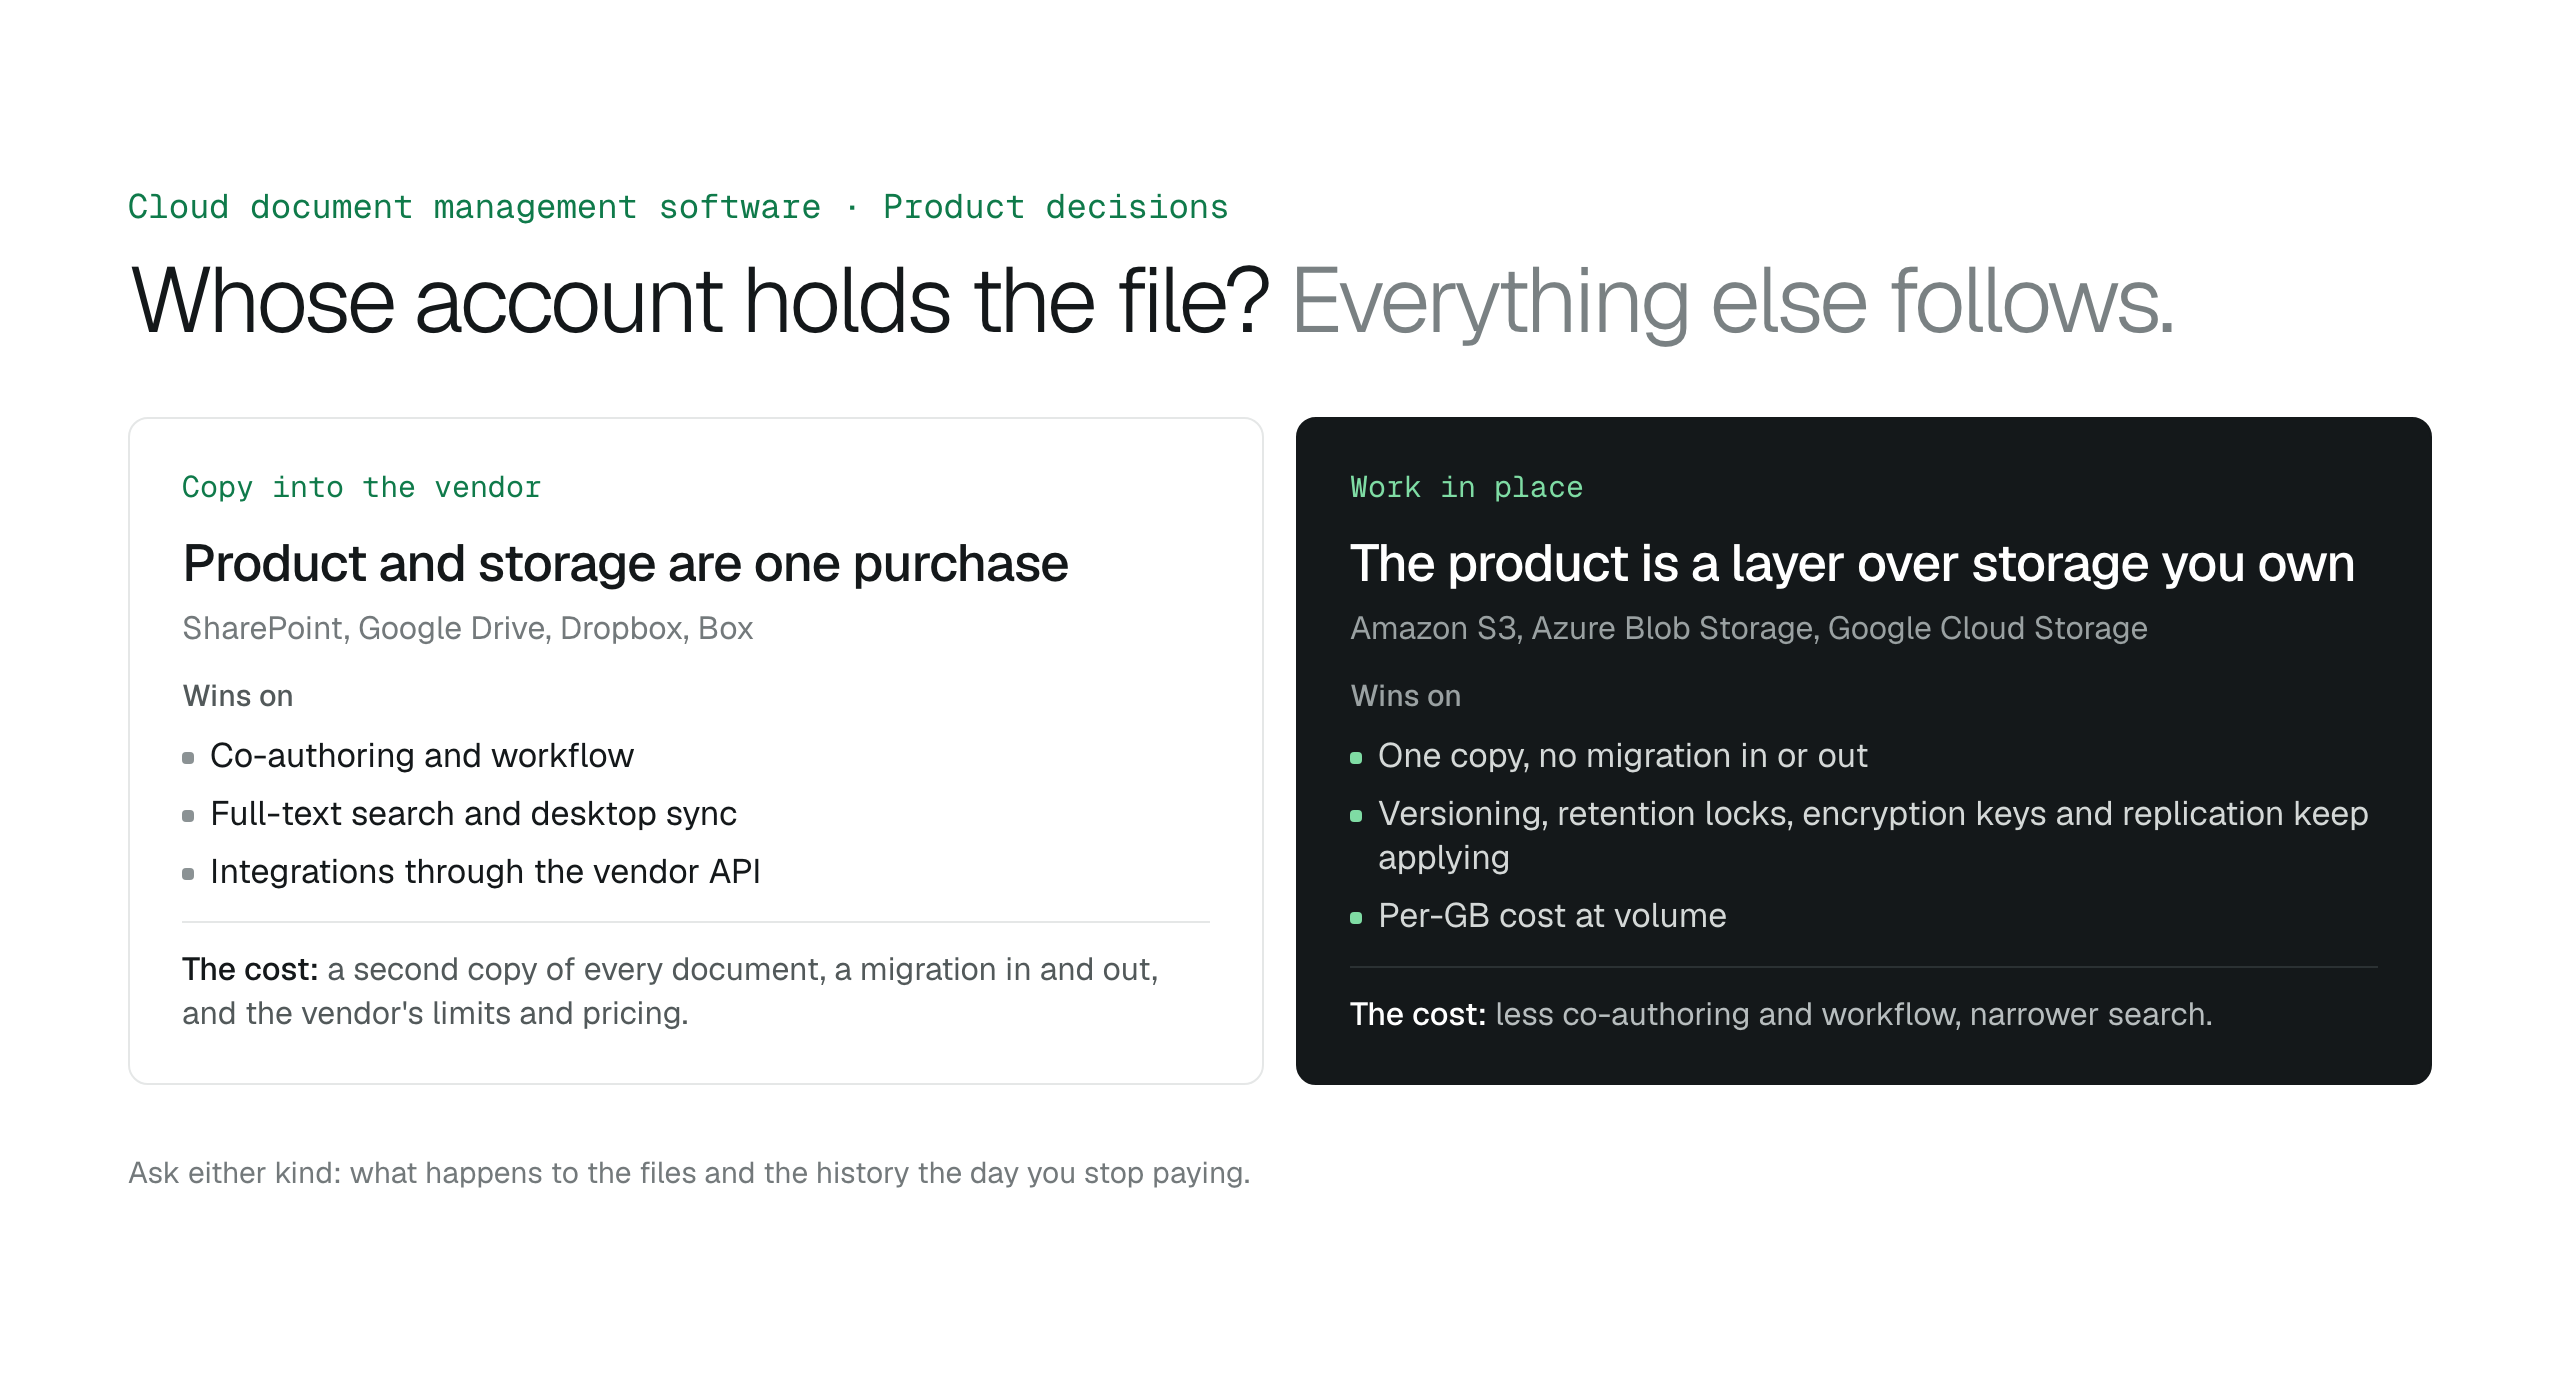
When choosing cloud document management software, decide whose account should hold the file before you compare features. If your documents are authored in a productivity suite by people with accounts in it, buy the suite. If they already live in object storage you own and most people need to find, read and share rather than co-author, add a layer over the bucket instead of migrating into someone else’s.
The best cloud document management software for you depends first on whose account holds the files. If your documents already live in your own cloud storage, such as Amazon S3, Azure Blob Storage or Google Cloud Storage, choose a tool that works on that storage in place, unless you need real-time co-authoring and workflow badly enough to keep a second copy in a vendor's system.
Search for document management software and you get a ranked list of products with overlapping feature grids. The grids are close to useless for choosing, because almost every product claims versioning, permissions, search, retention and audit, and almost every product means something slightly different by each word.
One question separates the options more cleanly than any feature comparison: whose account holds the file. Everything else, including the limits you will eventually hit, the shape of the bill, and what happens the day you leave, follows from the answer. This guide works through that question with the published limits for Microsoft SharePoint, Google Drive and Amazon S3.
What document management software is actually for
Strip the category down and a document management system does six things: it puts documents somewhere agreed, makes them findable, keeps a version history, decides who may see what, retains or disposes of them on a schedule, and records what people did. A seventh, collaborative editing, is often bundled in and is a genuinely different capability with different requirements.
Most teams looking at document management software are missing two or three of those six, not all of them. Worth naming which before you compare anything, because a product that solves your missing two while re-solving the four you already have is a migration project wearing the costume of a purchase.
The question that decides everything: whose account holds the file
In the vendor-hosted model, exemplified by SharePoint, Google Drive, Dropbox and Box, you upload your documents into storage the vendor operates. The product and the storage are one purchase, which makes everything work together and makes the boundary of the system the boundary of the vendor. Other systems reach your content through that vendor API, on their terms.
In the storage-first model, the files stay in storage you own, such as an S3 bucket in your own AWS account, and the product is a layer over it. You keep direct control of encryption keys, retention configuration, replication and cost, and every other system you run reaches the same objects natively. That includes AI assistants: Claude can read the same bucket through an MCP server. The product becomes a way of working with your storage rather than the place your content lives.
Neither is the correct answer in general. The useful test is where your documents are created and what else touches them. If almost everything is authored inside a productivity suite by staff with accounts in that suite, the vendor-hosted model has enormous gravity. If your files arrive from applications, pipelines, scanners, cameras or customers, and already sit in object storage for other reasons, storage-first means one copy instead of two.
Copy into the vendor, or work in place: the trade-off
A tool that copies files into its own storage gives you everything it was built around: its search index, its sync client, co-authoring, workflow and a single permission model. The cost is a second copy of every document. Someone has to run the migration, keep the two copies in step or retire one, and accept the vendor's limits, pricing and export process for the copy that people actually use.
A tool that works in place reads and writes the objects where they already are. Retention locks, versioning, encryption keys, replication and lifecycle rules you set on the bucket keep applying, and every other system that uses the bucket sees the same files. The cost is that the tool can only offer what it can build on top of object storage, which usually means less co-authoring and workflow and narrower search.
- Copying wins on: co-authoring, workflow, full-text search, integrations.
- Working in place wins on: one copy, storage controls that keep applying, per-GB cost at volume, no migration in or out.
- Ask either kind: what happens to the files and the history the day you stop paying.
What to check when the files already live in your cloud storage
When documents already sit in S3, Azure Blob Storage or Google Cloud Storage, some of the document management checklist is done before you buy anything. All three offer object versioning and write-once retention with legal holds: S3 Versioning and Object Lock, Azure blob versioning and immutable storage policies, Google Object Versioning and Bucket Lock. A product should leave those in force, not replace them with its own weaker copy.
The questions that decide the purchase are about the layer on top.
- Access: does it connect with a role or service identity you can scope and revoke, or does it ask for stored access keys?
- Content: does file content leave your account, and if it does, where does it go and for how long?
- People: can staff and clients sign in without a cloud console account, and get roles such as viewer or editor?
- Previews: which of your real formats open in the browser, including Office files, scans and video?
- Sharing: do external links expire, can you revoke them, and do they record who opened them?
- Audit: does the activity log name a person, not just the service role the tool uses?
- Search: does it search names, metadata or contents, and across one folder or everything?
- Clouds: does it support the storage you actually use, or only one provider?
What the documented limits actually say
The published limits are worth reading before a trial rather than after, because they describe the shape of each system. These are generous ceilings that most teams never reach, and the point below is not that any number is bad. It is that the numbers tell you what each platform was designed around.
Microsoft documents a 250 GB file upload limit and 25 TB of storage per site. A library can hold 30 million files and folders, but once a list, library or folder passes 100,000 items you can no longer break permission inheritance on it. The supported limit for unique permissions in a list or library is 50,000, with 5,000 recommended. Versioning tops out at 50,000 major versions, and Microsoft recommends syncing no more than 300,000 files in a single library. Moving or copying across sites is capped at 100 GB and 30,000 files per operation. Tenant storage is pooled: 1 TB plus 10 GB per licence, with more available to purchase.
Google documents individual files up to 5 TB, with files over 750 GB unable to be copied directly, and a 750 GB per user per 24 hour cap on uploads and copies. A My Drive folder holds up to 500,000 items, folders nest up to 100 deep, and an account can own up to 500 million items.
Amazon S3 documents no limit on the number of objects in a bucket and object sizes up to 50 TB, with the multipart specification putting the practical ceiling at 48.8 TiB. There is no per-seat storage pool, because storage is not sold by seat. What S3 does not document is any limit on permissions per prefix or versions per object, because it does not model those concepts the way a document library does: versioning is unbounded by object, and access is expressed in IAM policy rather than per-item permissions.
- Per-file ceiling: SharePoint 250 GB, Google Drive 5 TB, Amazon S3 50 TB.
- Permission granularity: SharePoint models per-item permissions with documented ceilings; S3 models access in policy, so there is nothing per-item to exhaust and nothing per-item to configure.
- Item counts: SharePoint 30 million per library, Google Drive 500,000 per My Drive folder, S3 unbounded per bucket.
- Storage pool: SharePoint and Google Workspace allocate per tenant and per licence. S3 has no pool; you pay per GB stored.
The pricing shapes differ, not just the prices
A seat-based suite bundles storage into the licence. Adding a terabyte usually means buying an add-on or more licences, and cold data that nobody has opened in four years costs exactly what hot data costs. That model is very kind to teams with many people and modest volumes.
Per-GB object storage is the opposite shape. Storage classes let rarely-touched data cost a fraction of active data, and a lifecycle rule moves it there automatically, so a large archive is cheap to keep and expensive only to retrieve in a hurry. Seats are then priced by the layer you put on top. That model is kind to teams with large volumes and a modest number of people who actually work with the files daily.
Work out which shape your organisation is before comparing monthly figures. Fifty people and 2 TB, and fifteen people and 300 TB, are different purchases even when the headline prices look similar.
What you give up by keeping files in your own bucket
Being straight about this matters more than the sales case. Real-time co-authoring, where several people type in the same document at once, belongs to the productivity suites, and an S3-backed workspace is not going to reproduce it. Neither is a mature workflow engine with routing, approvals and forms, nor the long tail of integrations an incumbent suite accumulates over fifteen years. Desktop sync is no longer on that list: BucketDesk Sync for Mac puts the bucket's folders in Finder.
Full-text search across everything is the other honest gap. S3 lists by key prefix and has no index of file contents, so searching inside documents means adding and paying for a search service. If your daily reality is several colleagues editing the same documents simultaneously, and finding things by a half-remembered phrase from inside them, a document suite is the better tool and this comparison should end there.
When storage-first is the right answer
- The files are already in S3 because an application, pipeline, camera or backup job put them there.
- Individual files are large enough that transfer and per-file ceilings are a real constraint.
- Retention or residency is configured at the bucket, and you want it to keep applying to every system that touches the data.
- Most people need to find, read and share documents rather than co-author them.
- You want one copy of the truth, and you do not want a migration to be the price of changing tools.
How to run the evaluation
Whichever direction you lean, run the trial against the three worst files you have rather than a tidy sample: the 4 GB scan, the spreadsheet with 40 tabs, and the format nobody can open. Feature grids agree with each other. Real files do not.
For any product that layers over your own bucket, four questions settle it. How does it obtain access, and can you revoke that access unilaterally? Does any file content leave your account, and if so, when and for how long? Which formats genuinely render in a browser, rather than downloading? And what lands in the activity log when someone views, shares or deletes something?
How to evaluate a browser-based S3 viewerS3 document management: what S3 does and what to addEnterprise content management on Amazon S3
Read the white paper
Document management on the S3 bucket you already own
BucketDesk works in place on Amazon S3 buckets. Access is a scoped IAM role you deploy with CloudFormation in your own account and can delete at any time; BucketDesk assumes it for short-lived credentials that expire on their own. People sign in to BucketDesk, and every action lands in Activity.
- Connect a bucket
deploy the CloudFormation role, and prefixes show up as folders with size, storage class and modified date.
- Preview and share
open PDFs, images and text in the browser, and on Standard add Office and media previews and expiring, revocable shares that record every open.
- Ask and restore
on Ultra, upload files, ask an open document questions with cited answers, and restore files or whole folders from Glacier.
Compare plansAsk about a pilotCompare these steps with the AWS Console
Minimum is free for one bucket. Standard is $100 a month and adds every bucket you have, unlimited viewers, Office and media previews and expiring share links. Ultra is $350 a month with a one-month free trial. Search matches the start of a file name in the current folder, and real-time co-authoring and workflow belong to the productivity suites.
Primary sources
- Microsoft: SharePoint limits ↗
- Google: Storage and upload limits for Google Workspace ↗
- AWS: Amazon S3 objects overview ↗
- AWS: Multipart upload limits ↗
- AWS: Understanding and managing Amazon S3 storage classes ↗
- AWS: Locking objects with S3 Object Lock ↗
- Microsoft: Immutable storage for Azure Blob Storage ↗
- Google Cloud: Bucket Lock ↗
- Google Cloud: Object Versioning ↗
Discussion
0 comments · open to guests · moderatedLiked this? Get the next article by email. No schedule, no digest, one click to leave.